Chapter 2. Linguistic analysis
We have seen that we can quite easily process large amounts of text with our program. We would certainly not want to count the numbers of characters in War And Peace by hand, and getting a computer to do this for us helps.
But why would we want to know the amount of characters in the first place? In reality, the plain number of characters itself is not often that interesting. But it gets more interesting once we start counting words and sentences and analysing them. Then we get into the area of linguistic analysis, which can be used, for example, to draw conclusions about the author of a written work.
A famous case concerns the works of William Shakespeare. A passionate debate has raged on and off at least since the 19th century about the authorship of Shakespeare’s work. While theories that another author has written all of Shakespeare’s works are almost certainly untrue, and are usually dismissed by serious scholars, debates about individual works are quite valid. There are several written works where authorship is unclear: either works attributed to Shakespeare where authorship is not proven, or unattributed works that may have been written by him.
It gets even more complicated: In the 17th and 18th century, it was not uncommon for theatres to commission for existing plays to be padded out by paying other writers to add scenes or acts to other authors' plays to make them longer. Many scholars believe that Shakespeare’s plays contain parts that may not have been written by him.
Linguistic analysis has been used as one tool to provide some evidence in this debate. It is based on the observation that this analysis can detect a personal style in the use of words, which can then be used – in a way similar to a linguistic fingerprint – to identify the author. It alone cannot give conclusive answers, but it can add interesting pieces of evidence for scholars. See, for example, Shakespeare by the Numbers[1] from the Shakespeare Oxford Fellowship.
Another example where linguistic analysis is used is to determine the reading complexity of written texts. Various algorithms exist to determine a "reading ease score" for a given text which expresses how hard or easy it is to comprehend. This may be used to choose appropriate books to study at school for specific age groups, or to make sure that important instructions provided with medication are not too complicated to be understood by the majority of the population.
One thing all forms of linguistic analysis have in common is that counting characters is not enough. At a minimum, we have to be able to identify and count words and sentences. So let us go on and investigate how to do this now, and then calculate a "reading ease" score for our documents.
Exercise 2.1 Let us jump ahead a bit and see where we are going with this. Open the project text-analysis-v5. This is the completed example which we will develop in this chapter. It is not important to understand the code at this stage. Run the program and look at the output: Which of the three books analysed do you think is the easiest to read? How is this represented in the printed output?
Close this project again, and open your version which you developed in the previous chapter (or use text-analysis-v3 if you do not have your own). We will continue to work from there.
2.1. Counting words
Counting the number of words in a text is very easy, because Python strings have a method called split, which splits the string into words. It will return to us a list of strings in which every element is an individual word from the original string. We can use it like this:

words = text.split()Note that this is a method of the string object (not a free-standing function) so we call it using the string variable, a dot, and then the method name.
To be precise: The split method splits the original string at every occurrence of whitespace. Whitespace is any space, TAB character or line break. Punctuation characters will not be treated specially, so that, for example, this sentence would be returned containing the word "example," (including the comma as part of the word.) If we wanted to analyse specific words, we would have to remove the punctuation characters. However, for counting words, this is not a problem.
Once we have received the list of words, we can obtain the number of words just by looking at the length of the list – it has one element per word. The built-in len() function, which we have seen earlier to count characters in a string, can also tell us the length of a list:

number_of_words = len(words)This is all that is needed to count and then print out the number of words.
 The built-in len() function can be used to return the length of a list.
Exercise 2.2 Implement the counting of words in your own project. Print out the number of words as part of your analyse_text function.
2.2. Again: using functions to improve code structure
While we add functionality to our program, our functions tend to become longer and longer. In our case, the analyse_text function has now become quite lengthy.
Long functions (or a long sequence of code in the "My code" section) make a program hard to read, and hard to understand. If a program is hard to understand, it is much more likely that errors creep in, or that we have difficulty extending or changing the program.
Our goal should always be to write short, concise, focussed functions. (The technical term for this is "cohesion": we aim to write cohesive functions.) The guiding rule is that every function should be responsible for one single clearly defined task.
Every function should be responsible for one single well-defined task.
Looking at our analyse_text function, we can summarise what it does like this:
-
It prints out the length of the text (the number of characters).
-
It counts and prints the number of non-space characters.
-
It counts and prints the number of punctuation characters.
-
It prints out the number of words in the text.
As we can see, these are four separate tasks. None of them really depends on the others; they are quite separate.
Following our rule of functions doing a single task, it follows that these four tasks should all be in separate functions. Creating this structure does indeed create a much more readable program, which will be easier to understand and maintain. Make this improvement in your own code by doing the following exercises.
Exercise 2.3 Create four new functions for the four separate tasks listed above. Make sure you name these functions appropriately, so that the name describes what they do. Move the code to implement each task into the body of the corresponding function. Then rewrite your analyse_text function to call these four functions. Test your program to make sure it still works; it should now do the same it did before these changes.
One further improvement we can make is to modify our new helper functions to calculate their results and then return them (instead of printing them). This separates the calculation logic from the printing, and leaves it the task of the analyse_text function to decide how to print the results. The function to calculate the number of words, for example, might then look like this:
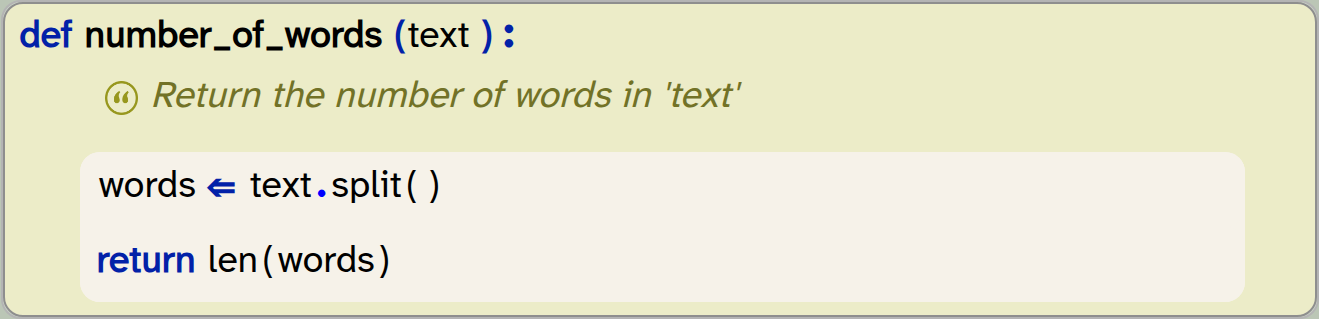
def number_of_words(text):
    """Return the number of words in 'text' """
    words = text.split()
    return len(words)
The analyse_text function can then simply call this function and print out its result.
Exercise 2.4 Modify your four new helper functions to calculate their result and return it as a function return value, using the return statement. Print out the result in the analyse_text function.
Exercise 2.5 You will notice that your own function to calculate the length of the text in characters just makes one call to an existing function (the len() function). In this case, your own function may not be necessary. You can remove this function and call the len() function in analyse_text instead.
Exercise 2.6 The project text-analysis-v4 in the book projects contains all the changes discussed here so far. Look at it and compare your own solution to this one. Have you done anything differently? Can you spot anything that you can improve?
The tasks carried out in this section of the book did not change the functionality of our program. It does exactly the same as before. So were they worth doing?
In these tasks, we did not add functionality, but we instead cleaned up the implementation and made our code more readable and easier to modify and extend. Just all-round nicer.
In general, when we are programming, we should alternate between these two phases: add new code, then clean up the code we wrote and make it as nice as we can. Many novice programmers do not bother to do this. The result would be that we end up with long, messy, hard-to-read code, and at some point we will get stuck with a program that we can no longer understand and maintain. Being a good programmer means not only to write correct code, but also to write readable code.
What we have seen here is that defining separate functions serves two distinct purposes: Firstly, when we have defined analyse_text as a separate function, we have seen that we can then call this function two or three times, without needing to write the code two or three times. Thus functions serve to support reuse: We can reuse the same code repeatedly and easily.
Secondly, with the functions we have created in this section, we have used them to support modularity. We divide our whole program into small and simple building blocks (the functions), which we can then assemble to solve larger tasks. This helps us solve problems by dividing larger problems into smaller sub-problems, and also serves to keep our code clear and readable.
Using functions supports code reuse: Once a function is written, it can be called multiple times, in different places, without the need to write the code twice.
Using functions supports modularity: Breaking up our code into separate functions structures our program into logical tasks. This makes the code easier to understand and easier to modify.
2.3. Counting sentences
Counting the number of sentences in a text is a bit more involved than counting words, because there is no built-in string method to do this. But it is not very difficult. In fact, it is quite similar to something we have already done: counting punctuation characters.
In this case, we do not want to count all punctuation characters, but only those that end a sentence. As a starting point, we can just assume that the full stop, exclamation mark or a question mark end a sentence, and thus just count those characters. We can do this again, as we have done before, by using a for-loop and an if-statement to count those characters:
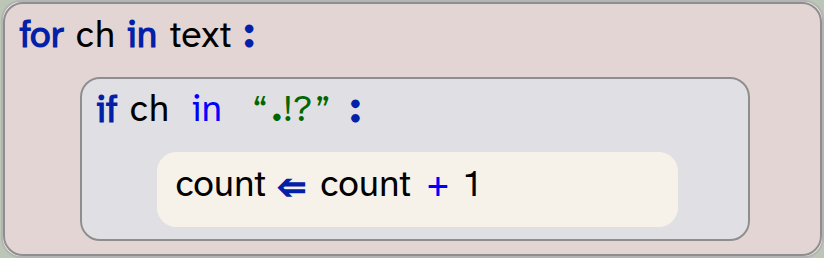
for ch in text:
    if ch in ".!?":
        count = count + 1
Exercise 2.7 Implement the counting of sentences in your project. Follow the same structure as before: Create a separate function that returns the number of sentences in a text as a return value.
Of course, the counting of sentences in this way is not entirely accurate. If, for example, the text includes three dots … – this would be counted as three sentences, which is not correct.
There are two ways to deal with this: The first is to refine the function that counts sentences to take this into account. The second is to live with this approximation. In a long text, this inaccuracy will be small, and for many purposes our approximate (almost correct) result will be good enough. So the solution to choose depends on the context.
What we intend to do is to calculate a text complexity score. For this purpose, this approximate result is good enough, and we choose to leave it as it is.
2.4. Counting syllables
A syllable is a single sound in a word when spoken. For example, "the" has one syllable, "happy" has two syllables, and "computer" has three. Syllables can be used for some calculations of text complexity, which we will explain in the next section. To use the number of syllables in a calculation, first we need to be able to count them.
Counting syllables in the English language (and most other languages) is much more complex than counting words or sentences. Because of this, we will use another approximation here: We will use a heuristic (which is essentially just a rule of thumb), which says that in the English language on average the number of syllables in a word is the number of characters, divided by 3.2, rounded to a whole number.
In Python, we can write this like this:

num_syllables = round(len(word) / 3.2) In this code, we can see that we again use the len() function to get the number of characters in a word, we use the / operator for division, and we see that there is a built-in round() function to round the result to a whole number for us.
The round(n) function can be used to round a decimal number to an integer (a whole number).
Exercise 2.8 Do some research on the round() function. You can do this by doing a web search for "Python round". What is its optional second parameter?
Exercise 2.9 Implement a function in your code to calculate syllables in a word, using the formula above. Test it by calling it with some words. How often is it accurate?
Now that we can compute the (approximate) number of syllables in a word, we can calculate the number of syllables in the whole text by just looping over all words again, and adding up the syllables of each word:
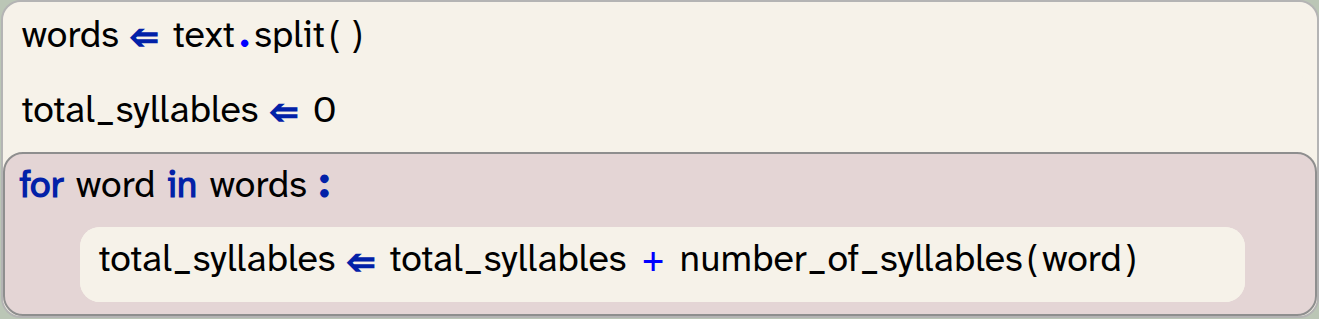
words = text.split()
total_syllables = 0
for word in words:
    total_syllables = total_syllables + number_of_syllables(word)
Note that this is different to just applying the formula to the length of the whole text, because the rounding for each word affects the result.
Exercise 2.10 Add code to your program to calculate and print the total number of syllables in your text.
2.5. Text complexity
The last thing we will do in this chapter is to calculate the text complexity using a reading ease score. Now that we can calculate all sorts of statistics of our texts, this is quite straightforward.
Several different formulas are in use by professionals to do this. We will use one of the most commonly used methods, the Flesch reading ease score. (If you want to find out details about this, do a web search.)
The Flesch reading ease score is calculated with the following formula:

This formula will give us a score between 0 and 100. This score can then be used to classify the difficulty of the text, using the following table:
| Score | Readability | Who can understand it |
|---|---|---|
90–100 |
Very easy |
Understandable by an average 11-year-old student |
80–90 |
Easy |
Conversational English for consumers |
70–80 |
Fairly easy |
Understood by most 12-year-olds |
60–70 |
Standard |
Plain English. Easily understood by 13- to 15-year-old students. |
50–60 |
Fairly difficult |
School students in 10th to 12th grade |
30–50 |
Difficult |
University graduates |
< 30 |
Very difficult |
Specialists, experts |
Looking at the formula, we can see that we need only three values as input, all of which we have already computed: The total number of words, the number of sentences, and the number of syllables in the text.
This means that we can now write a function to calculate the reading ease score, and call it with these values:
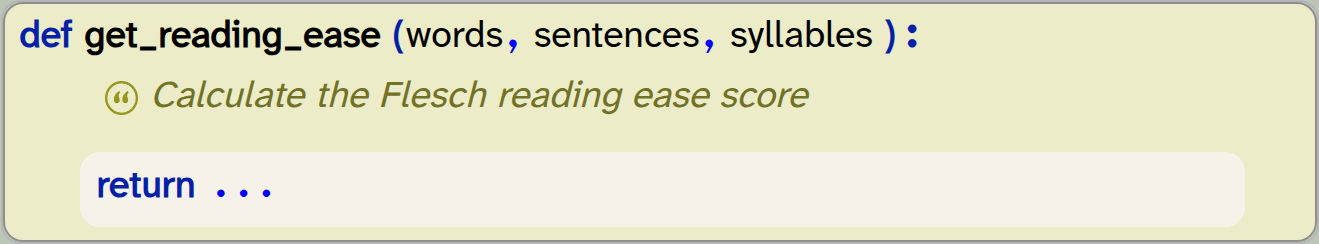
def get_reading_ease(words,sentences,syllables):
    """Calculate the Flesch reading ease score"""
    return ...
The body of this method here is incomplete – we leave it as an exercise for you to fill it in.
Exercise 2.11 Write a function to calculate the Flesch reading ease score as shown here. Return the correct score using the formula shown above.
Exercise 2.12 The Flesch reading ease calculation regards parts of a sentence separated by a comma or a colon as a separate sentence. Adapt your function which calculates the number of sentences so that it takes these two characters (,:) into account to create separate sentences for the purpose of our calculation.
Exercise 2.13 Print out the reading ease scores for the text documents analysed in your program. (Hint: the score for Pride and Prejudice should be 73.85. If you see this result, then your program is correct.)
Exercise 2.14 You may have noticed that the output for your reading ease score shows many digits after the decimal point – many more than is useful. Print the result rounded to two decimal places. You can achieve this in one of two ways: You can either use the round() function (round (value, 2) will round value to two decimal places), or you can add the formatting option :.2f after a value in an f-string (e.g. f"Value: {value:.2f}" will do the same.)
Exercise 2.15 What is the reading ease score of the sentences
"Programming is fun. I enjoy it."
What is the score for the sentences
"The systematic development of correct computer code instills feelings of pleasure. It creates unquestionable sensations of distinct and surprising enjoyment."
Exercise 2.16 Use some texts of your own, and run your analysis on those. You can either find the full text of books on Project Gutenberg, a website that provides out-of-copyright books, or you can use, for example, the last essay you wrote for school work. In each case, you have to make sure that the text is saved in plain text format. If the text comes from the web, make sure you download a "Plain Text" (or UTF-8) file. If it is your own document, and you wrote it in a word processor, make sure to save the file in plain text format before using it with your Python project. You can usually do this using the "Save As" menu item and selecting plain text format for saving. If you are unsure how to access your own files, have a look at Appendix C: Working with data files.
As always, an implementation of the project as discussed here is available in the book projects; it is called text-analysis-v5.
2.6. Summary
In this chapter we have continued our analysis of text. We have seen how we can identify not only characters, but words and sentences, and how to use this information to assess the reading ease of a piece of writing. This text analysis is a first example of data science, of which we will see a bit more in a later chapter.
Secondly, we have again seen examples of improving the structure of our code. We have used functions to create a program that is modular and readable. This is important to create code of good quality, as it makes it easier for others reading our code to understand it.
-
The built-in len() function can be used to return the length of a list.
-
Every function should be responsible for one single well-defined task.
-
Using functions supports code reuse: Once a function is written, it can be called multiple times, in different places, without the need to write the code twice.
-
Using functions supports modularity: Breaking up our code into separate functions structures our program into logical tasks. This makes the code easier to understand and easier to modify.
-
The round(n) function can be used to round a decimal number to an integer (a whole number).
Oscar winners
Have a look at the oscar-winners project: It reads a text file that contains information about all Academy Award (aka "Oscar") nominees from 1950 to 2025 and then prints out the winner for each year.
Have a look at this program and figure out how it works. (Also have a look at the text file itself to see what information it contains.)
Once you understand how it works, you may try to extend the program to let the user choose what they want to see. In addition to the list of winners it could also be: the winner for just a single year; all nominees for a given year; all films by a given director (and the year they were nominated); all movies with a given substring in the title (e.g. "midnight"), and so on.
The next thing you could try is to find another text file that contains information separated by commas and write a similar analysis and summary program for that one.