Chapter 5. Generating text: Making improvements
We have seen, in the previous chapter, that we can produce text output by generating bigrams from a source text and then using those to generate each next word. We have also seen that this text looks only very superficially like English – the sentence structure is very obviously wrong, and the words do not really fit together very well.
We will now work on improving this.
5.1. Improving the model
What we have called our "model" is a simple list of bigrams: a list of words that can follow another given word. We have used this to produce our sequence of words. This looks a little bit like English, but the word sequence is frequently odd and a bit too random. What, for example, should be the next word if the previous word was "your"? Could you predict a reasonable next word?
It is obvious that the possibilities are very wide, and you are unlikely to come up with a word that makes much sense in any specific context.
But how about predicting the next word if the previous words were "How is your"? Now the options for a reasonable next word are much narrower, and you can probably come up with a few choices that could make sense ("How is your mother?", "How is your headache?", etc.)
The idea we get from this observation is quite straightforward: Maybe we can improve things if we look at longer sequences of words.
5.2. Bigrams to trigrams
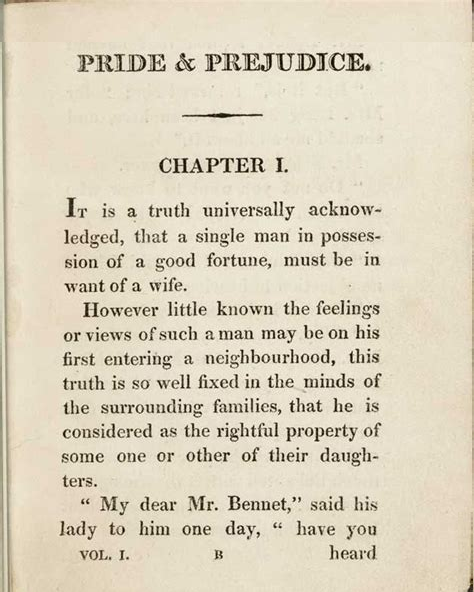
Let us start investigating this idea in a simple form at first: instead of looking at bigrams – pairs of words – we look at trigrams: sequences of three words. Consider, for example, the text from Figure 5.11:
It is a truth universally acknowledged,
that a single man in possession of a
good fortune must be in want of a wife.
The trigrams from this text are all the three-word sequences that occur in the text. We can write them down in a list; they are:
(It is a)
(is a truth)
(a truth universally)
(truth universally acknowledged,)
(universally acknowledged, that)
(acknowledged, that a)
(that a single)
…
Once we have a list of trigrams, we can produce new text with a similar idea as before: we predict the next word. This time, however, we do not only look at the preceding word – we look at the two preceding words. Given the two previous words in a text, we then find the trigrams where the first two words match the two preceding words, and we select the third word from one of the matching trigrams as the next word in our generated text.
In Python, each of the trigrams is stored as a tuple of length 3, and all the trigrams – as before – in a list. Generating the trigrams is quite straightforward, since the built-in zip function can also merge three lists together (or, in fact, any number of lists).
As before, we have to generate lists with the words shifted by one word, and we do so by slicing off the first word for the first copy, and the first two words for the second copy (Figure 5.12).
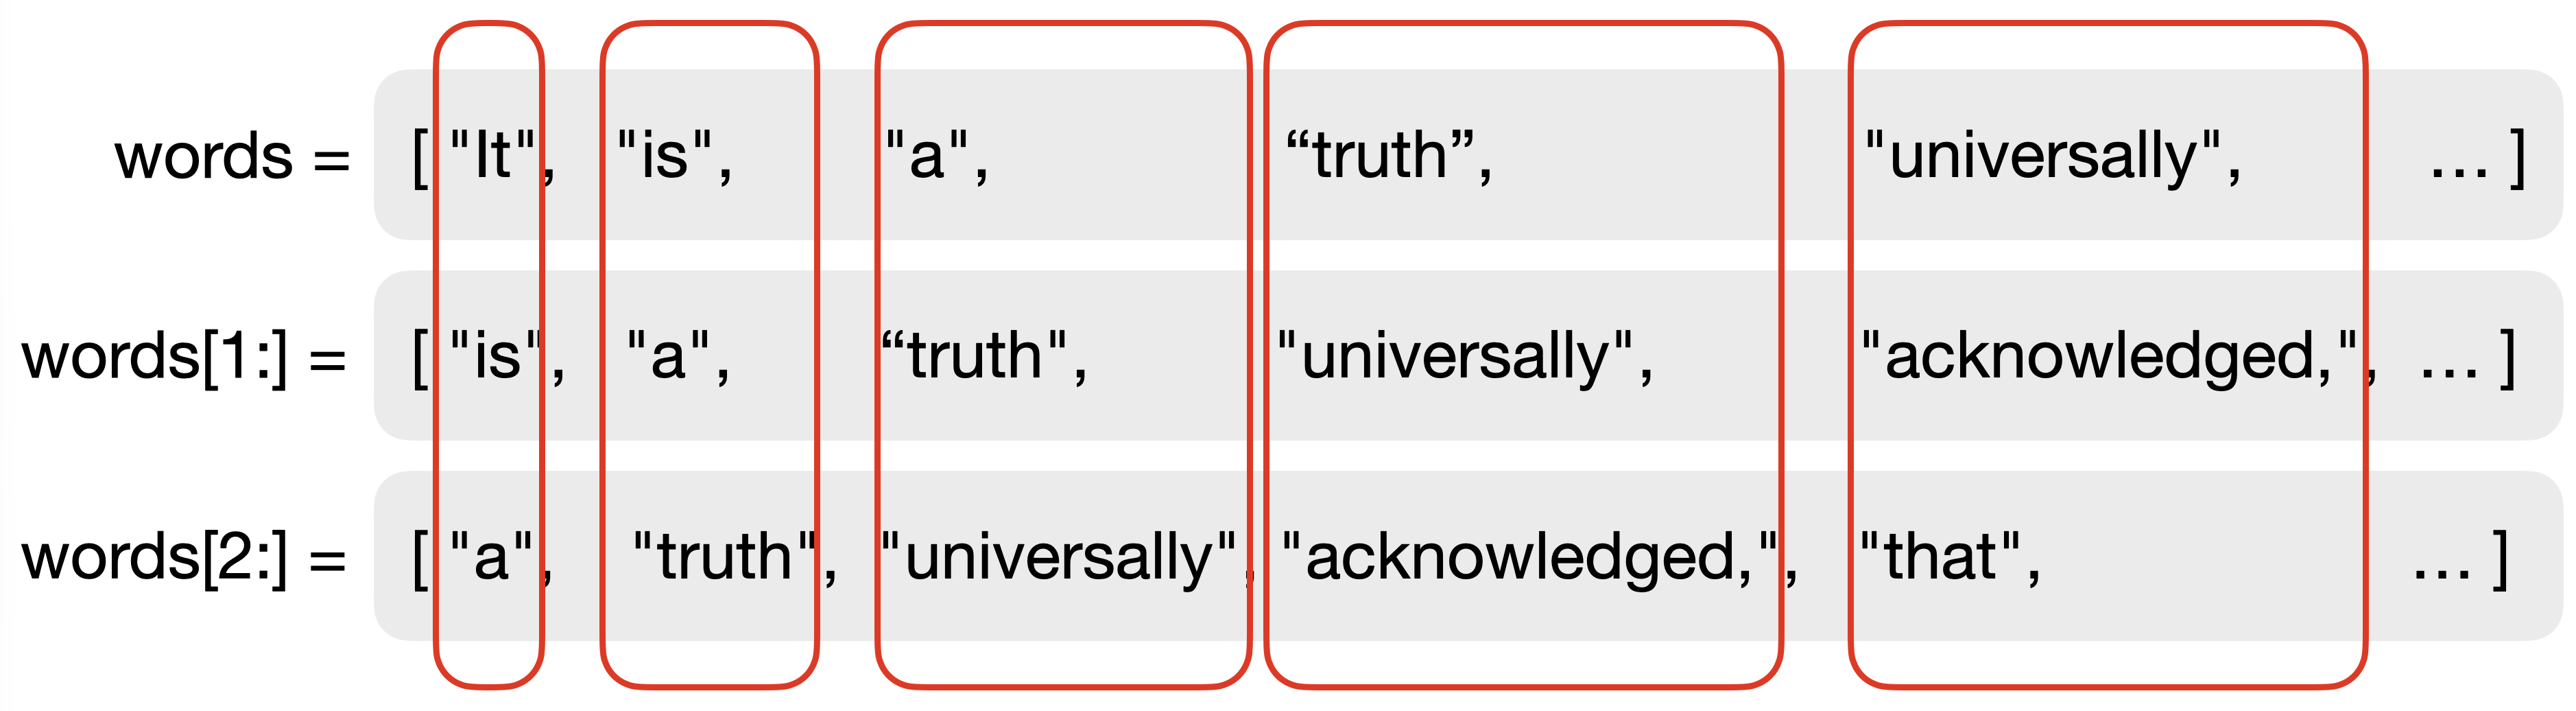
In our program, generating the trigrams then looks like this:

trigrams = zip(words,words[1:],words[2:]) The zip function can merge not just two lists, but any number of lists. With n lists, the zip function produces a single list of n-tuples.
Change your entire program to work with trigrams now, using the following list of exercises.
Exercise 5.1 Change your make_bigrams function to make_trigrams. In the function, generate and return a list of trigrams. (Make sure to update the function comment.)
Exercise 5.2 Change your generate_next_word function so that it generates the next word from two previous words and your list of trigrams. Return the last word from a trigram where the two first words match the previous words.
Exercise 5.3 Adapt your test code in your "My code" section to set two start words, and then generate the next 80 words from there. It works well if you use fairly generic start words, such as "It" "was".
If you find these exercises difficult, you can compare your attempt to our implementation in text-generation-v3.
If you have done the exercises so far – how is your output now?
You will see that this simple improvement of our "model" – going from bigrams to trigrams – significantly improves the quality of the text it produces. Now the output looks almost like grammatically correct English! That is quite astonishing for such a simple algorithm.
Of course, the sentences are still gibberish – they don’t mean anything, and you cannot read any sense into them. We discuss below how Large Language Models (LLMs) manage to do better than this.
We can now, of course, go even further with the same idea: instead of using three-word sequences, how about four-word sequences? Or five-word sequences? This idea takes us from trigrams to n-grams, and we will discuss it below. But first, let us look at another idea to improve our system: improving our training data.
5.3. Improving the data
There is a very simple change that we can make to improve the quality of our system: use more data.
In real LLMs, the models are trained on millions or billions of documents. Many of them are fed any text you can access on the Internet, and much more besides.
We will not use that amount of text, but we have two files available that contain just a bit more than a single book. The Strype file system folder includes a file called /books/fairy-tales.txt, which holds the full text of 65 fairy tales by the Brothers Grimm, and another file called /books/sherlock-holmes.txt, which has the text of 27 Sherlock Holmes stories (three books and 24 short stories). Try your program with these texts as the training data.
Exercise 5.4 Change the file you read in to build your trigrams. Use the file /books/fairy-tales.txt. Run your program. How is the output changed from before?
Exercise 5.5 Do the same again with the file /books/sherlock-holmes.txt as the training data. How does the output differ now?
A version of the project with these changes is in the book projects as text-generation-v3.
If you did these experiments yourself, you will have noticed two things: Firstly, using longer texts to "train our model" improves the quality of the output. The more text we feed in, the more closely the output resembles actual language. We have not, in fact, used very much data. Even the "sherlock-holmes" file contains only about 330,000 words. This is minuscule in the context of large language models, but it already starts to deliver quite surprising results.
And secondly, the content of the text we feed into the model determines the language and style of the text that is produced.
These two observations lead to two very significant issues: Firstly, with the aim to be able to produce any kind of output, large AI companies have been scanning all writing they could get access to. This includes, for example, millions of published books. For the performance of the system, this is great: you can tell your AI system to write a short story in the style of Stephen King, and it will very competently do this. It has read in all existing Stephen King stories, and so it can copy the style amazingly well.
The problem is that these stories are under copyright, the AI companies have not legally licensed them, and Stephen King has not explicitly given his permission.
So, is this legal?
Currently, this is an undecided question. The AI companies argue that it falls under the "Fair use" clause in copyright law, since the source works are not reproduced directly. Many authors argue that this is copyright theft, since their own original hard work is being used – and being commercially exploited for profit – by other companies without their permission.
The second problem is the sheer amount of data involved, and the amount of processing power and electricity required to process it. Reading and transforming the "sherlock-holmes" file is trivial, and a standard laptop can easily do it. But processing the amount of data involved in real LLMs – more text than the content of all the libraries in the world combined – requires so much processing power that the environmental impact is immense. Power is not only needed to train the model (this is only done infrequently), but for every single question that an AI system is asked to answer. Even the most trivial query requires huge processing power and consumes large amounts of energy.
To cope with this, AI companies are building huge data centres in many areas of the world, full of processors which only serve AI queries from users. A single data centre can consume as much energy as a city of a million people. For the environment, this is a disaster; it creates significant new problems for the goal of reducing the environmental damage which we cause.
Exercise 5.6 Research "fair use" in copyright law. What is it? What does it allow, and what does it not allow?
Exercise 5.7 Do you think AI companies should be allowed to use copyrighted books without the author’s permission? Name some arguments for both sides of this argument. What about films or TV programs? What about using the likeness of a famous person?
Exercise 5.8 Try to find out where the nearest data centre is to the place where you live. Try to find some information about the amount of energy a data centre consumes. If you can, try to find this information for the data centre nearest to you.
Exercise 5.9 Try training the system with some of your own writing. Find as many pieces of text you have written, copy them together into a single plain text document (there is no need to maintain formatting), and then see what your system produces from your own words. (Again, refer to Appendix B for information how to access your own files.)
One other interesting observation is this: Our algorithm needs absolutely no understanding of the words it produces. If you feed in a text in Spanish, it will happily produce Spanish output. Or any other language written in our alphabet. (Try it!) The outcome is quite impressive, but it shows that the system has no understanding of the text at all – it just shuffles words around.
5.4. Trigrams to n-grams
We already mentioned the next obvious improvement above: using even longer sequences of words to match before selecting the next word. But instead of making a version now for sets of four or five words, let us generalise our algorithm: we can write a function that can produce n-grams (groups of n words) for any given n.
An n-gram is a sequence of n consecutive tokens from a list, such as n words from a text.
We are getting into quite advanced territory now. Let us start, this time, by analysing and studying a solution to this problem.
Exercise 5.10 Open the project text-generation-v4. This project shows an implementation for our algorithm using n-grams (with a flexible n) instead of bigrams or trigrams. Read the program text and write down all statements in the code that are new or unclear to you.
Let us go through the program and investigate the interesting aspects more closely.
We can see that the make_ngrams function now has two parameters: the source text (text) and the n to specify the length of our n-grams:
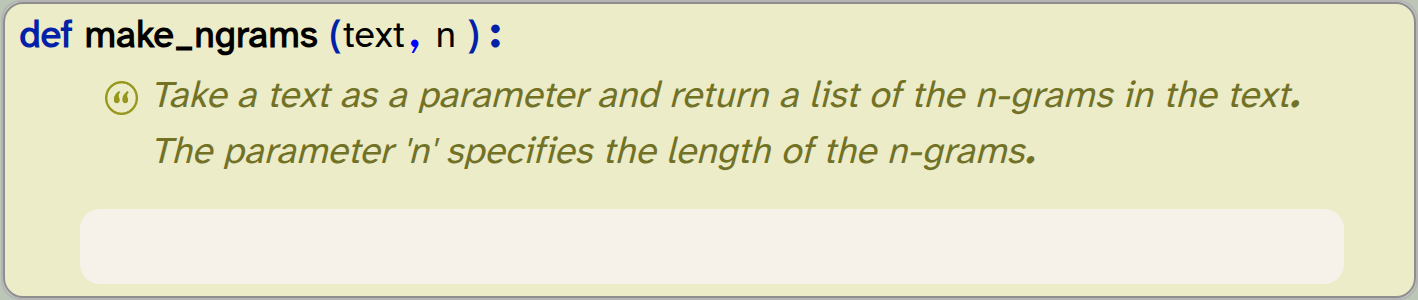
def make_ngrams(text,n):
    '''Take a text as a parameter and return a list of the n-grams in the text. The parameter 'n' specifies the length of the n-grams.'''
    pass
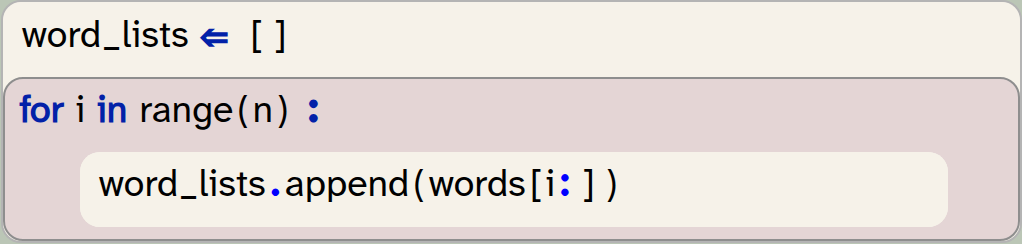
To create our n-grams, we now need n lists, each shifted by one word. We do this by creating a list of lists, and adding the individual lists to it:
word_lists  = []
for i in range(n)  :
    word_lists.append(words[i:])
Think through this code carefully: You will be able to see that it creates n separate lists, each with a different number of words cut off at the start by slicing, and then adds these lists to another list of lists (word_lists).
The next line contains a construct we have not seen before:

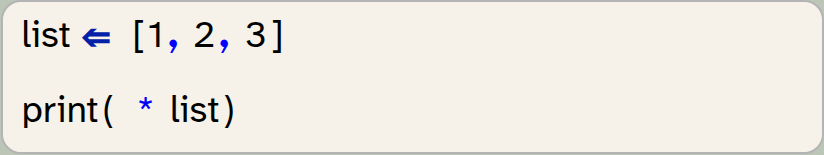
ngrams = zip( * word_lists) Here, we have a list, preceded by a single asterisk (*). The * operator, when written as a prefix before a list, is the list unpacking operator: It takes all the elements of the given list and presents them as separate parameters. For example:
list = [1, 2, 3]
print (*list)
is the same as writing

print (1, 2, 3)The elements of the list are unpacked into separate parameters, and then passed to the print function. In the same manner, the statement
ngrams = zip( * word_lists)is the same as writing

ngrams = zip(word_lists[0], word_lists[1], word_lists[2], word_lists[3])if the length of the list is 4. The power of this operator is that it works for any length of a list. We could not write the fully written out alternative without knowing in advance how long the list is.
A unary *, written before a list, is the unpacking operator. It turns a list into separate parameters. Thus, print( * [1,2,3]) is the same as writing print(1,2,3). The unpacking operator also works with tuples and other iterable types.
In the generate_next_word function, the most interesting statement is as follows:
if ngram[:-1] == prev_words  :
    following.append(ngram[-1])
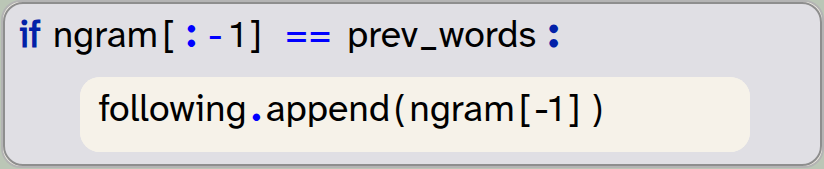
Here, we make use of the fact that we can use a negative index both for slicing, and for accessing elements in a tuple. If we have a tuple

t = ("ab", "cd", "ef", "gh")and then we create a slice t[:-1], we are slicing from the beginning of the tuple to one position before the end (-1). The resulting tuple will be
("ab", "cd", "ef")
Similarly, we make use of the fact that we can write t[-1] to refer to the last element in a tuple. Taken together, the if-statement above checks whether the n-1 first words of the n-gram match our previous words, and if they do, append the last word of the ngram to our results list.
Study this code until you are comfortable with it. Don’t be surprised if this looks difficult or confusing at first – this is getting into more advanced areas than we have seen before, and it is not surprising if understanding this is not easy at first.
Another few observations are worth making about this version of our project:
-
We are now providing more than one source file as our training text. Look at how this is done.
-
In the program, we are using 4 as our length for the n-grams. Therefore, we must provide an initial prefix of 3 start words to start off our algorithm.
-
When we print out the initial three start words, we use the unpacking operator again, this time for a tuple.
-
An obvious thing to try now is to use values greater than 4 for our n. This is now easy in principle, but we would soon discover that this does not work well with the amount of text we are using as our training data. We would not find enough n-grams of length five or six in the text without using much, much more data, so we are reaching the limit of this technique here. The section at the end of this chapter gives a brief discussion how LLMs deal with this problem.
-
An obvious improvement now would be to start with n-grams for a given n, and if no match is found, fall back to (n-1)-grams, then to (n-2)-grams, and so on. We leave this as an exercise for the reader.
Exercise 5.11 Run the program several times and observe the output. In going from length 3 to length 4 in our n-grams, has the quality of the output improved?
Exercise 5.12 Add more text to the training text. Observe how this changes the output.
You will see that the produced text now looks pretty good, even though we are still using quite a simple algorithm, which we can write in a few dozen lines of code. Before we wrap up this chapter, we will look at two more internal improvements we can make to our program.
5.5. Using list comprehensions
In this section, we will not make any improvements to the functionality of the program. Instead, we will just write the same functionality using different Python constructs.
If you like, you can safely skip this section. If you are mainly interested in learning about the principles of programming, then the solution we have written so far is perfectly good; we have used lists, loops and if-statements to build and process our data structures, and this is how we could do the same in many different programming languages. It gives us a good understanding how this algorithm works.
If, however, you are interested in the specific details of Python, then read on. Python has some constructs that allow us to write the same code more concisely. This version makes use of list comprehensions, which is an elegant way in Python to achieve the kind of processing we have used here.
Exercise 5.13 Open the text-generation-v5 project. Run it, then study its code. Find all the statements that look unfamiliar to you.
The statements most likely to be new to you have a form we have not seen before. For example:

following = [ngram[-1] for ngram in ngrams if ngram[:-1] == prev_words]This is called a list comprehension, and it is a construct that can create a new list by filtering and mapping elements from a source list. Let us assume we have a list of numbers:

list = [32, 4, 77, 71, 6, 99, 101]We can then create a new list that holds all elements from the original list which are greater than 10 by writing the following:

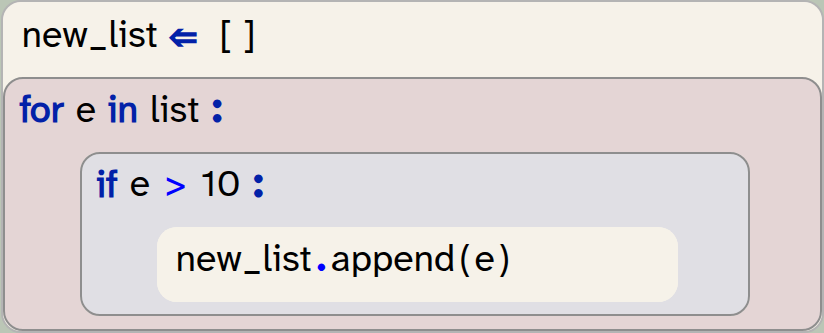
new_list = [e for e in list if e>10]This code is equivalent to writing the following without list comprehensions:
new_list = []
for e in list:
    if e>10 :
        new_list.append(e)
Using list comprehensions has a number of advantages:
-
The code is shorter than before. We can achieve the same result with fewer statements. While beginning programmers often find this syntax confusing at first (and may prefer the longer loop version), practised Python programmers typically find the list comprehension version more elegant. After programming in Python for a while, programmers become familiar with this syntax, and it becomes as easy to read as other statements.
-
The version using list comprehensions is typically faster than the loop version. Internally, the system can optimise the code and achieve better efficiency.
We will not discuss this variant in detail here. If you aim at becoming an expert Python programmer, then you should study this construct more closely. You can do this by reading Appendix C: Python list processing, and then studying this version of the project.
A list comprehension is an alternative construct to filter and process elements from a list to create a new list. It is a Python construct that allows efficient and elegant expression of these kinds of tasks.
5.6. A performance improvement
One last change that we will briefly present here is another improvement that is not essential, but may be interesting to study. Again, this is an advanced topic, and you can safely skip it if you like.
This version of the project is provided in the program text-generation-v6. You can open and study this version.
The main difference in this version is that we are now using a dictionary, instead of a list, to hold our n-grams.
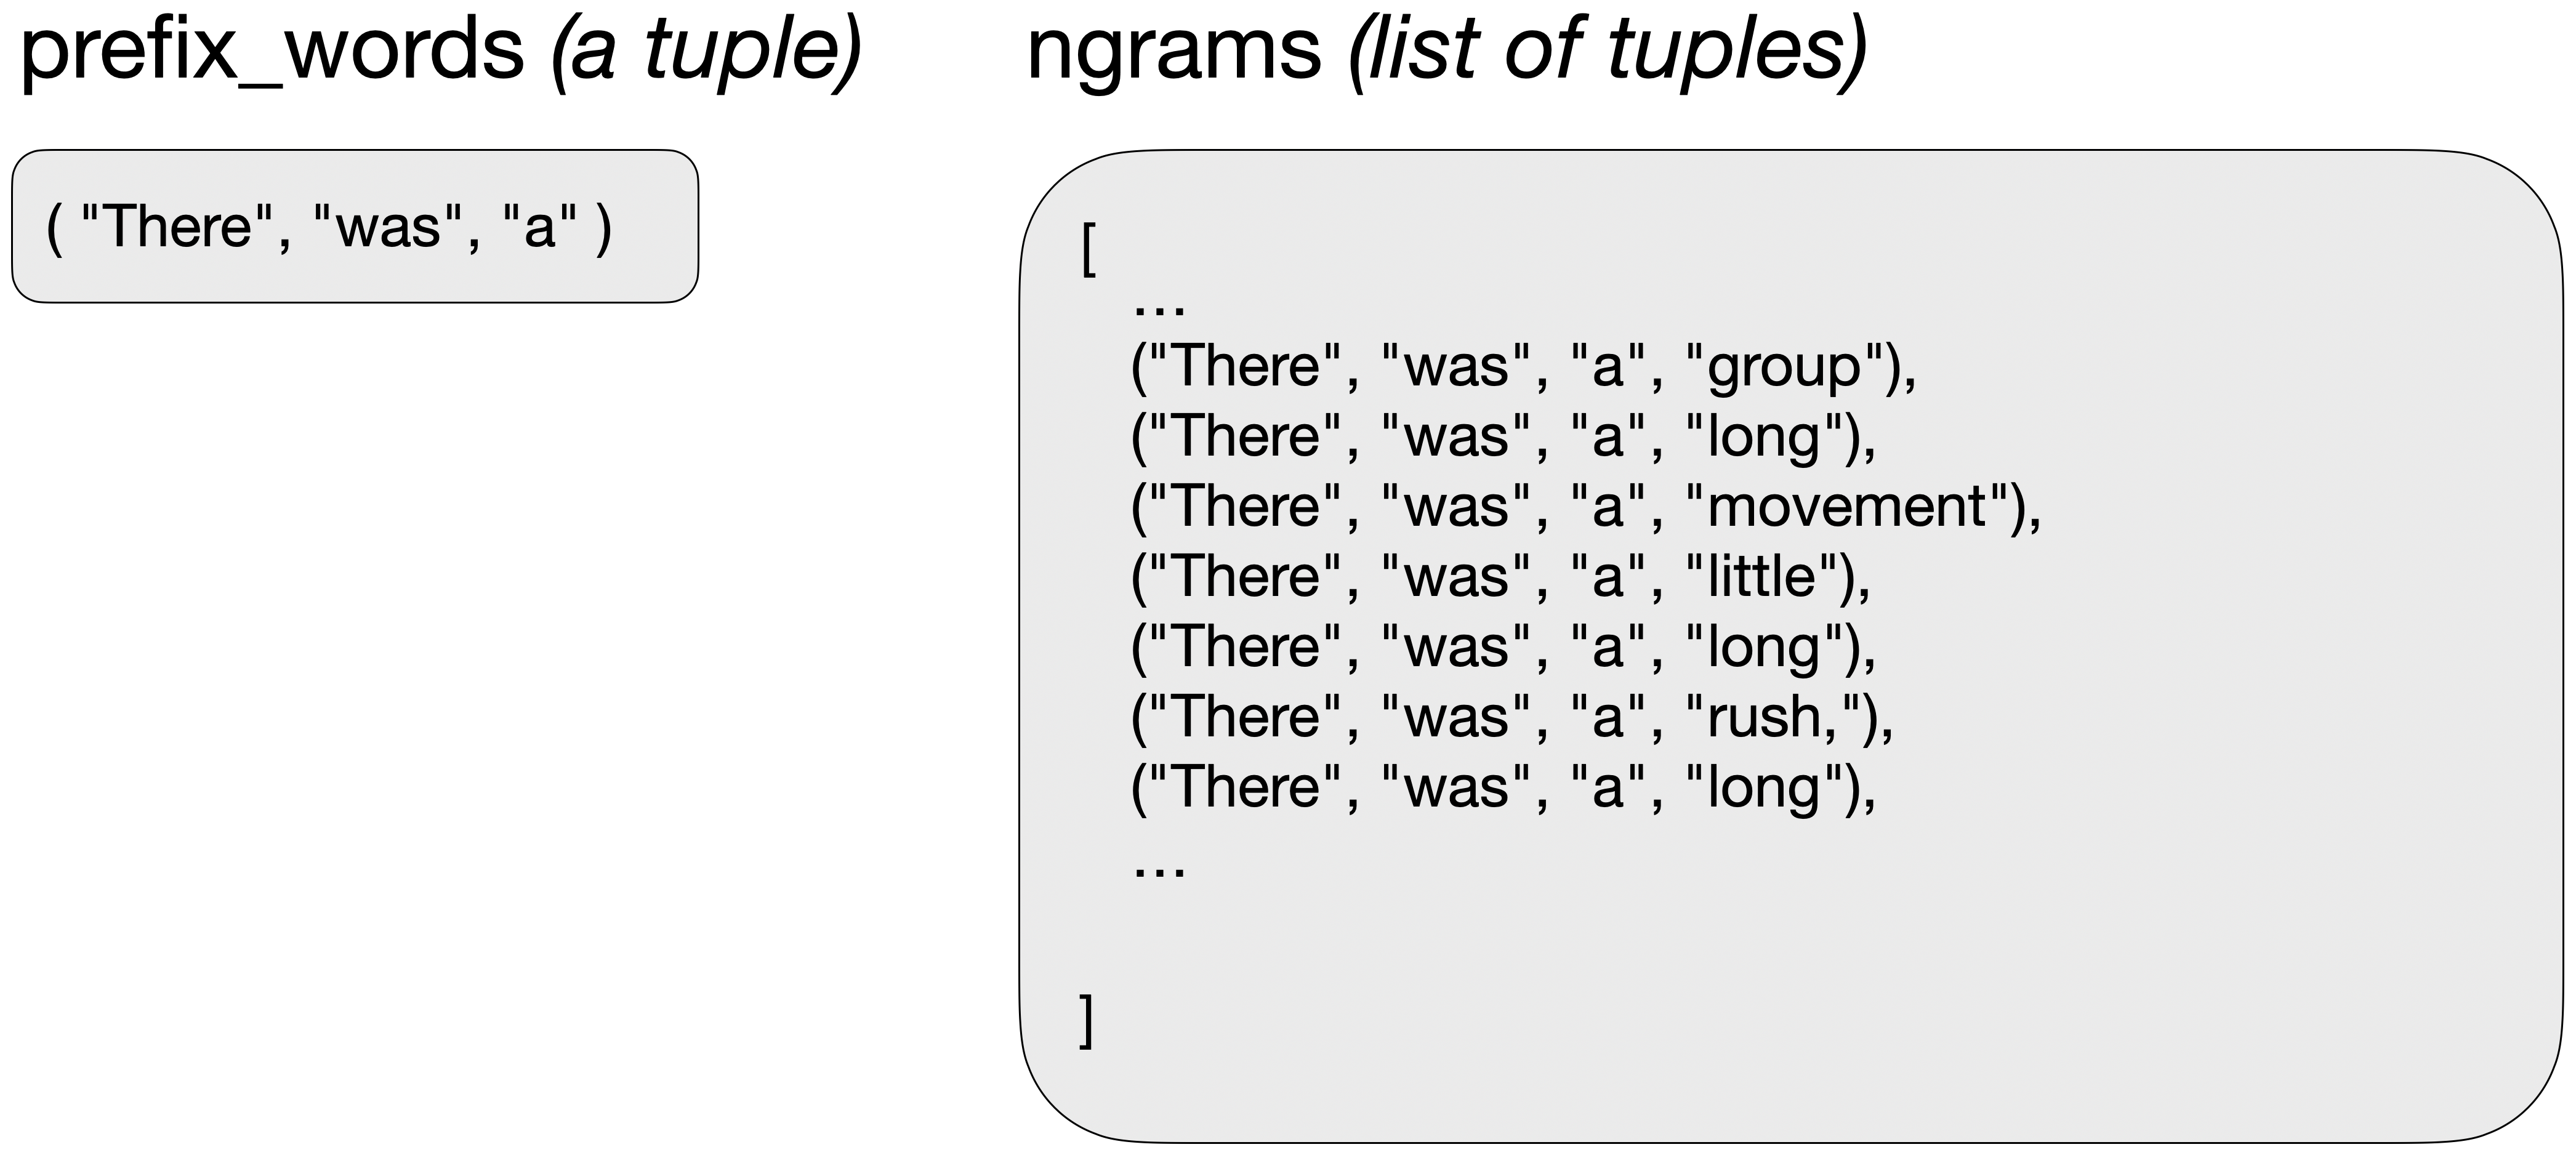
Previously, we had a list of n-grams, and every time we wanted to find a next word, we would provide a prefix tuple with the previous words, and then search our list for n-grams where the first n-1 elements match our prefix tuple (Figure 5.13). As a result, each new word involved searching our entire n-gram list again.
In our new version, we instead create a dictionary. The keys in the dictionary are the n-1 words of each n-gram, and the value for each key is a list with all the possible following words (Figure 5.14).
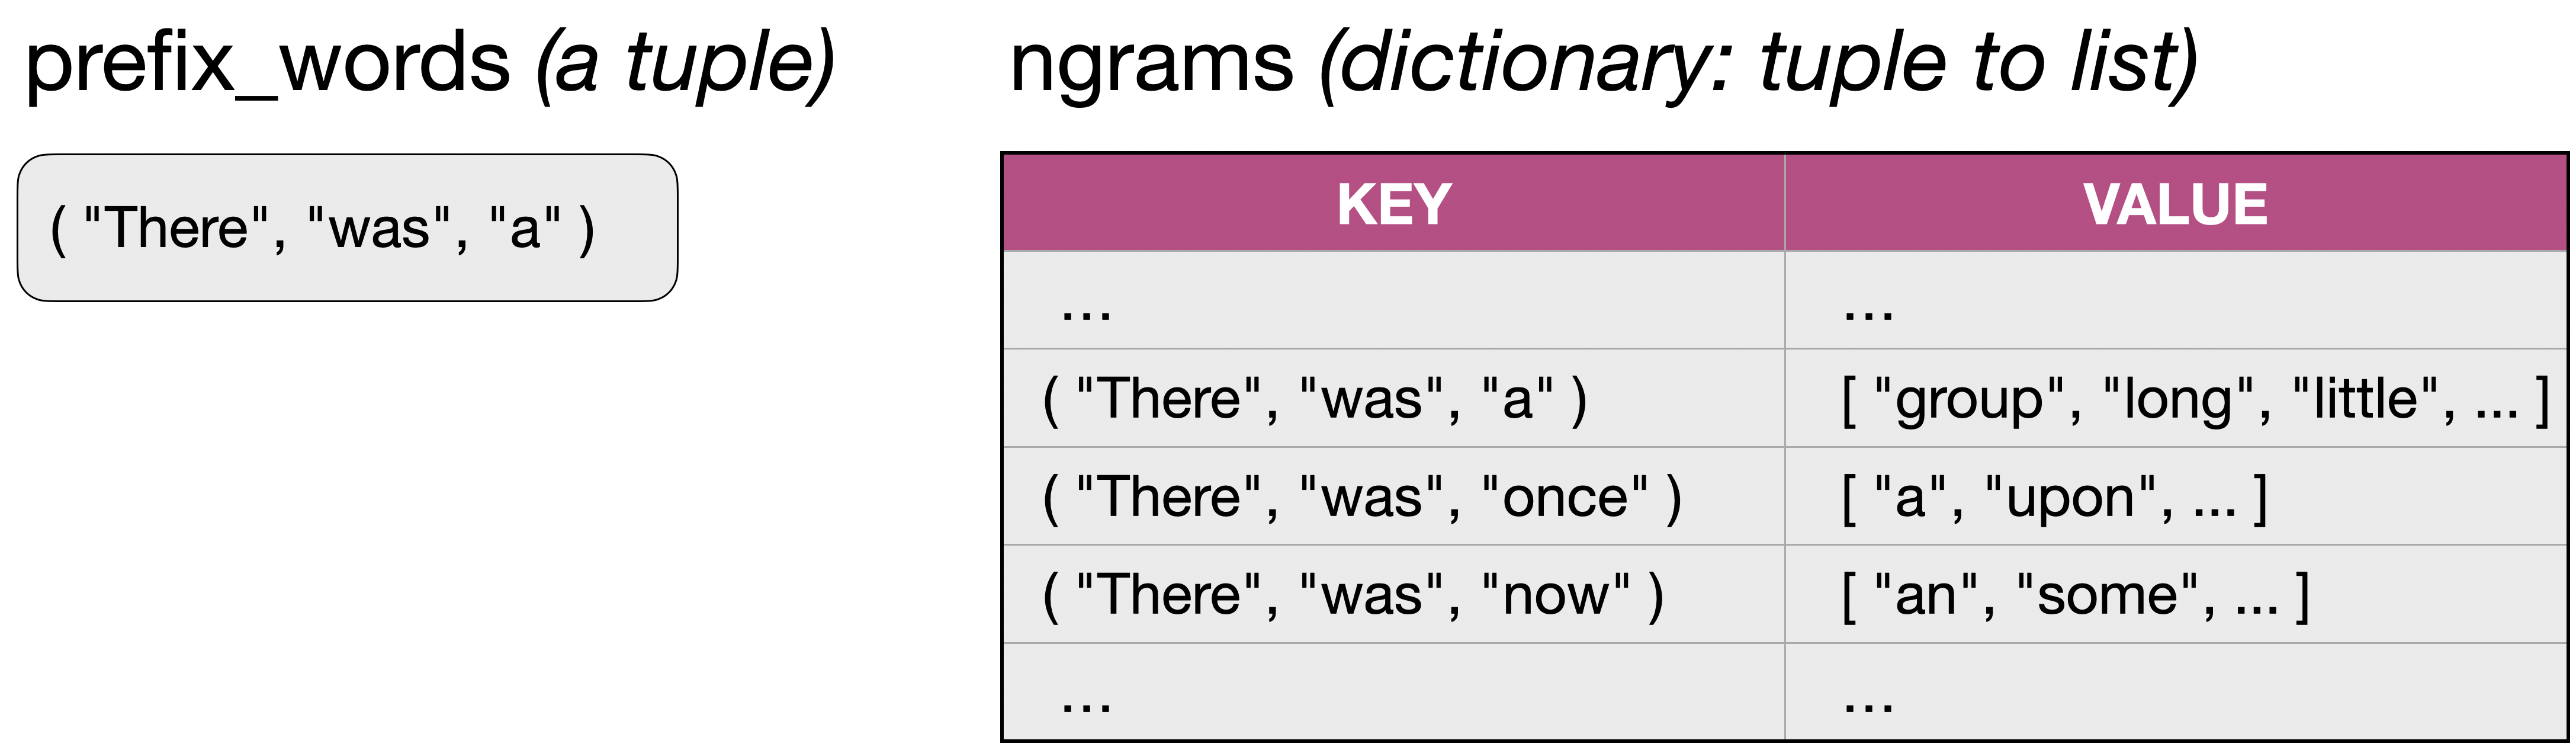
Now, finding each next word consists of one dictionary lookup, and then a random selection of the following word from the list of possible words. Since a single dictionary lookup is much faster than searching a whole list, this version performs much better.
Exercise 5.14 Use a previous version of this project to generate 500 words. Time how long this takes. Then do the same with this version of the project. How do the times compare?
Lookup in a dictionary is much faster than searching through a list.
Discussing this solution in detail is beyond the scope of the book, and we leave it to the interested reader to study this version. It is included mainly for especially keen or advanced readers – you can safely progress without studying it.
5.7. Large language models
We have seen that our model does not come close to the abilities of current AI systems, and there are many reasons for this.
Firstly, there is room to improve our current system. One idea is again simple: use longer chains of words. We have used n-grams with a small n – no more than 4. If we had much more source text (such as a whole library), we could work with longer n-grams.
Using more contextual words does indeed improve the performance of these systems. And the project that we investigated in this chapter does indeed give a glimpse into the history of text processing.
Until the mid-2010s, n-gram-based systems were considered the state of the art in text processing. They were successfully used in predictive text systems and speech recognition.
After that, text processing systems evolved significantly, and modern LLMs have a number of important differences that make them more effective:
-
While n-grams use a fixed size window of the last n-1 words, LLMs use flexible and much larger windows – often thousands or millions of tokens. Doing this, they can make long-range connections, important for staying on a topic, making arguments, and so on.
-
N-gram systems typically work with lists of words. In LLMs, each word is represented not by its actual letters, but by a large, multidimensional vector that encodes many aspects of the word. This includes semantic and contextual information, which helps to make many more connections. For example, it may know that "cat" and "dog" are somewhat related words, even though their letters are entirely different. This helps the model to generalise and transfer knowledge between related concepts. n-gram chains then do not have to match words exactly, but can look for closely related words.
-
LLMs are trained not by simply counting or storing the words and probabilities, but using neural networks, which expose much deeper connections between words. They also implicitly learn about grammatical structure and language patterns.
The resulting systems are known as generative pre-trained transformers (GPT). The full details of these are more complex than we can discuss here. But ultimately, they are generalisations of the simple system we have built here. Or in other words: An n-gram model is a special, extremely limited case of what a GPT transformer can represent.
N-gram systems, however, are not obsolete. They continue to be useful in predictive text, spell checking, speech recognition, and in document retrieval systems.
While our project here does not allow us to understand fully how LLMs work, it does give an insight into the core of the idea that underlies LLM-based AI systems. Perhaps most importantly: It is still the case that LLMs have no real understanding of the content and meaning of the text they produce, and are ultimately based on clever manipulation and prediction of language. These systems may state an entirely invented "fact" with the same confidence as an obvious truth.
AI companies are working hard to improve the reliability of LLMs. This tension, however, between our desire of trust and these systems, which ultimately just manipulate language, will remain at the core of the issue of reliability in AI systems for some time.
Exercise 5.15 Ask an AI system to produce the first 80 words of a short story inspired by Sherlock Holmes. Compare the output to that of your own system. What differences can you identify?
5.8. Summary
The implementation of the improved n-gram algorithm in this chapter has given us more practice with tuples and lists. We have seen how we can use these data structures very flexibly to solve a number of very different problems. While doing this, we have also gained an understanding of how text prediction systems can work, such as those used for predictive text in messaging apps.
We have, however, only scratched the surface of the possible uses of lists and other data structures. In the next chapters, we will look at the use of these classes in an entirely different context.
-
The zip function can merge not just two lists, but any number of lists. With n lists, the zip function produces a single list of n-tuples.
-
An n-gram is a sequence of n consecutive tokens from a list, such as n words from a text.
-
A unary *, written before a list, is the unpacking operator. It turns a list into separate parameters. Thus, print( * [1,2,3]) is the same as writing print(1,2,3). The unpacking operator also works with tuples and other iterable types.
-
A list comprehension is an alternative construct to filter and process elements from a list to create a new list. It is a Python construct that allows efficient and elegant expression of these kinds of tasks.
-
Lookup in a dictionary is much faster than searching through a list.
Beatbox
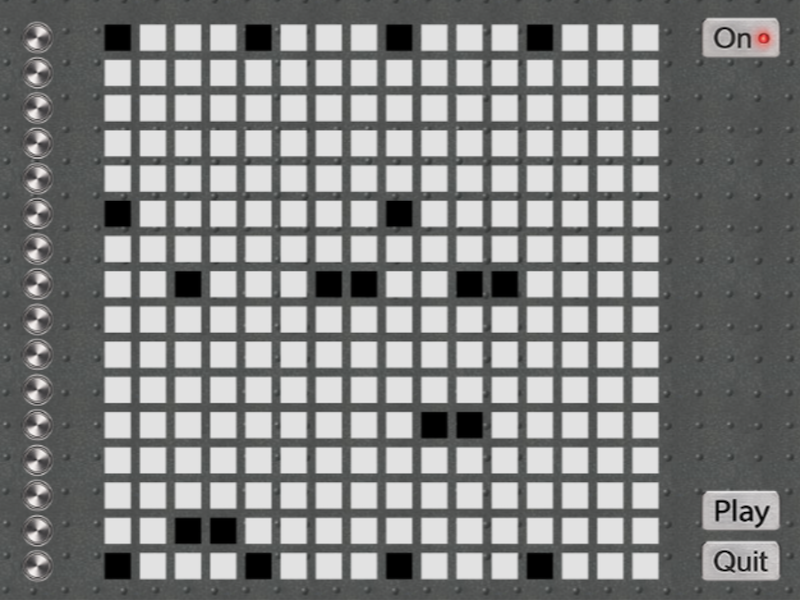
It might be interesting at this time to get back to a more graphical project – one using a graphical interface and sound. It might also be a nice change to work with a more interactive program again, rather than examples that process text files.
The topics we have studied so far – different types of collection classes and how they can be used and combined – are also highly relevant for more sophisticated graphics and sound projects. The example we are providing here – beatbox – gives you a good case study: it uses a list of percussion sounds, a list of lists to provide a two-dimensional grid, and stores tuples in actor tags to attach information to graphical actors.
It is well worth studying this example to become more familiar with the use of collections in other contexts.