Chapter 2. Introduction to dictionaries
We have set out the goal for the next step of our project in the previous chapter: we would like to count how often each word in a text occurs in the whole text. To do this, we now introduce a very useful new data structure: a dictionary. Through the project in this chapter, we will understand what a Python dictionary is and how we can use it.
2.1. Dictionaries
A dictionary (or dict, as Python calls this type internally) is a data structure that stores key/value pairs.
Every entry in the dictionary associates a key with a value, and we can look up the value by providing the key. An example is a list of phone numbers for your friends (Figure 2.3).
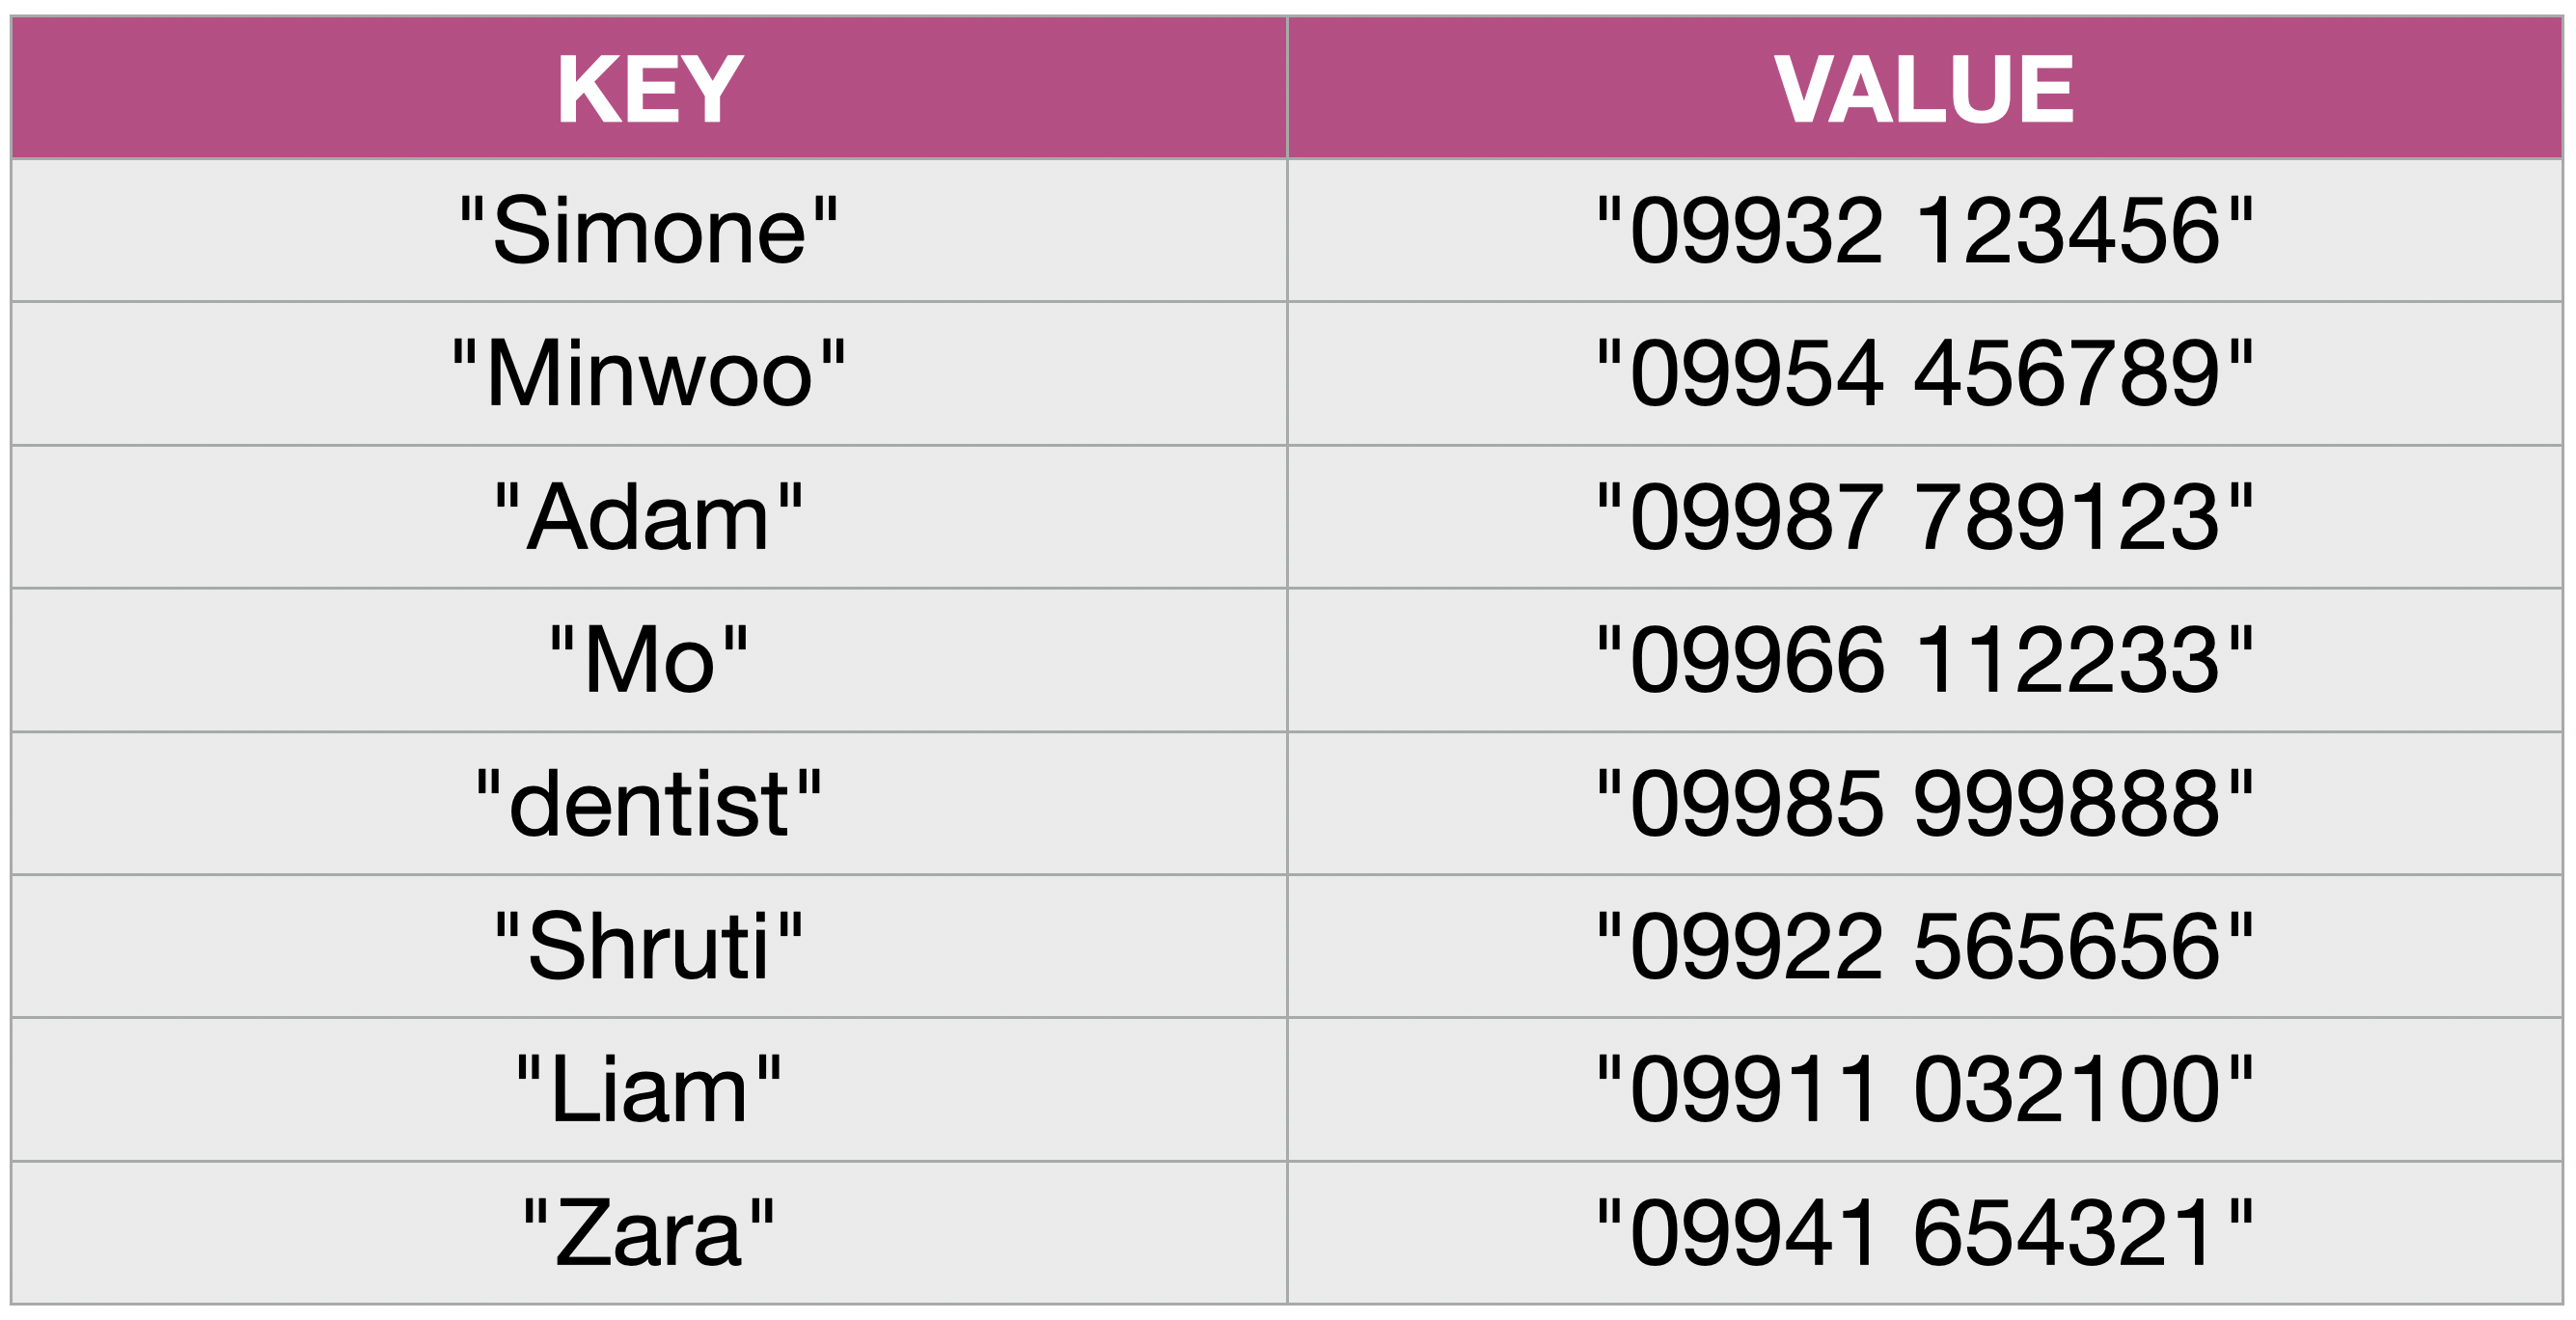
We see that we can think of a dictionary as a table with two columns. The first column holds the keys (here: the names), and the second column holds the values (the phone numbers).
We can then look up the value by providing the key. Let us look at an example how this works. Assume we have the dictionary shown in Figure 2.3 stored in a variable called phonebook. We can then write
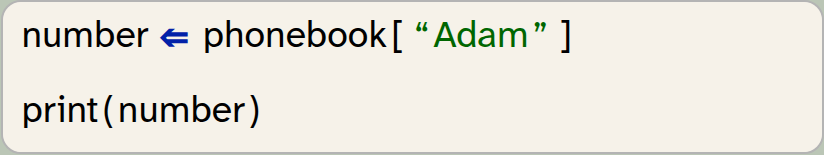
number = phonebook["Adam"]
print(number)
This will print Adam’s phone number. We use the key like an index in the dictionary, and we receive the associated value. This makes looking up a particular entry in the dictionary very easy.
We can also add more entries to our dictionary. For example

phonebook["Zola"] = "099777 885557"will add a new entry in the dictionary (a new row in the table) with the phone number for Zola. Again, we see that we use the intended key like an index in square brackets, and we just assign the value to create the entry.
Dictionaries are useful in many situations, and we are familiar with the concept from our daily lives. One important aspect is that they do not only work with strings. Both the key and the value may be any type we choose.
For example, your contacts app on your phone holds a dictionary that uses the name of a person as a key and all their details — email address, phone number, home address — as the value. (Here we can see that the value can be more than a single string: it can itself be a complex data type with several types of information). You use it by looking up the name, and it shows you the associated details (the value).
Other examples are a password file on a computer (associating usernames with passwords) or a shopping basket on a website that associates a product name with a count of the number in the basket. Perhaps the most familiar example is an English language dictionary (from which the Python data structure gets its name): The key here is a word, and the value is its definition. We can find a word in the dictionary to look up its definition.
 A dictionary is a data structure that holds key/value pairs. We can look up a key to find the associated value.
The last thing we need to know is how to create a dictionary. Python dictionaries are written with curly brackets: { }. Writing the curly brackets on their own creates an empty dictionary:

phonebook = {}We can also create a dictionary pre-filled with some data using a colon to separate keys and values, and a comma to separate the entries:

inventory = {"apples": 5, "oranges": 3, "kiwi": 8} Python dictionaries are written using curly brackets: { }. Writing a pair of curly brackets on their own creates an empty dictionary.
Before we go on to use a dictionary in our word counting function, let us do some simple exercises to become more familiar with dictionaries.
Exercise 2.1 Close your current project for the moment and create a new project for these exercises. In your new project, create a variable named phonebook and assign to it an empty dictionary. Print this variable to the console. What is the output?
Exercise 2.2 Add to the phonebook three entries with names and phone numbers of three of your friends or family. Print the phonebook again. What does the output look like?
Exercise 2.3 What does the len function return when you use it to check the length of your phonebook?
Exercise 2.4 What happens when you add an entry with a key that already exists? Experiment with this and then describe what happens.
Exercise 2.5 What happens when you add an entry with a value that already exists? Try this out.
Exercise 2.6 What happens when you try to look up a key that does not exist in the dictionary?
Exercise 2.7 What is the output of the following code:
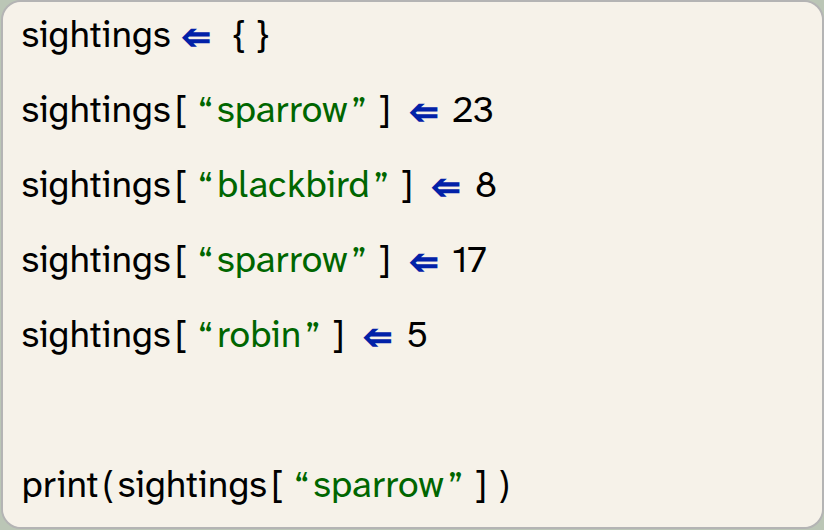
sightings = {}
sightings["sparrow"] = 23
sightings["blackbird"] = 8
sightings["sparrow"] = 17
sightings["robin"] = 5

print(sightings["sparrow"])
Exercise 2.8 With the same code as in the previous exercise, what is printed by the following line:

print(len(sightings))Exercise 2.9 How do you remove an entry from a dictionary? Do some research to find the answer.
A key in a dictionary is unique, but values can appear repeatedly. Inserting an entry with a key that already exists replaces the existing entry.
2.2. A dictionary of word counts
Let us now get back to the word counting problem in our thematic-analysis project from the previous chapter. We were at the point where we could count the frequency of a single word, and we need to figure out how to count the frequencies of all words. As we have stated above, a dictionary can help with this.
The idea is that we use a dictionary – let’s call it counts – with an entry for each word. We can use the word itself as a key, and use the value for the count (the number of times we have found the word).
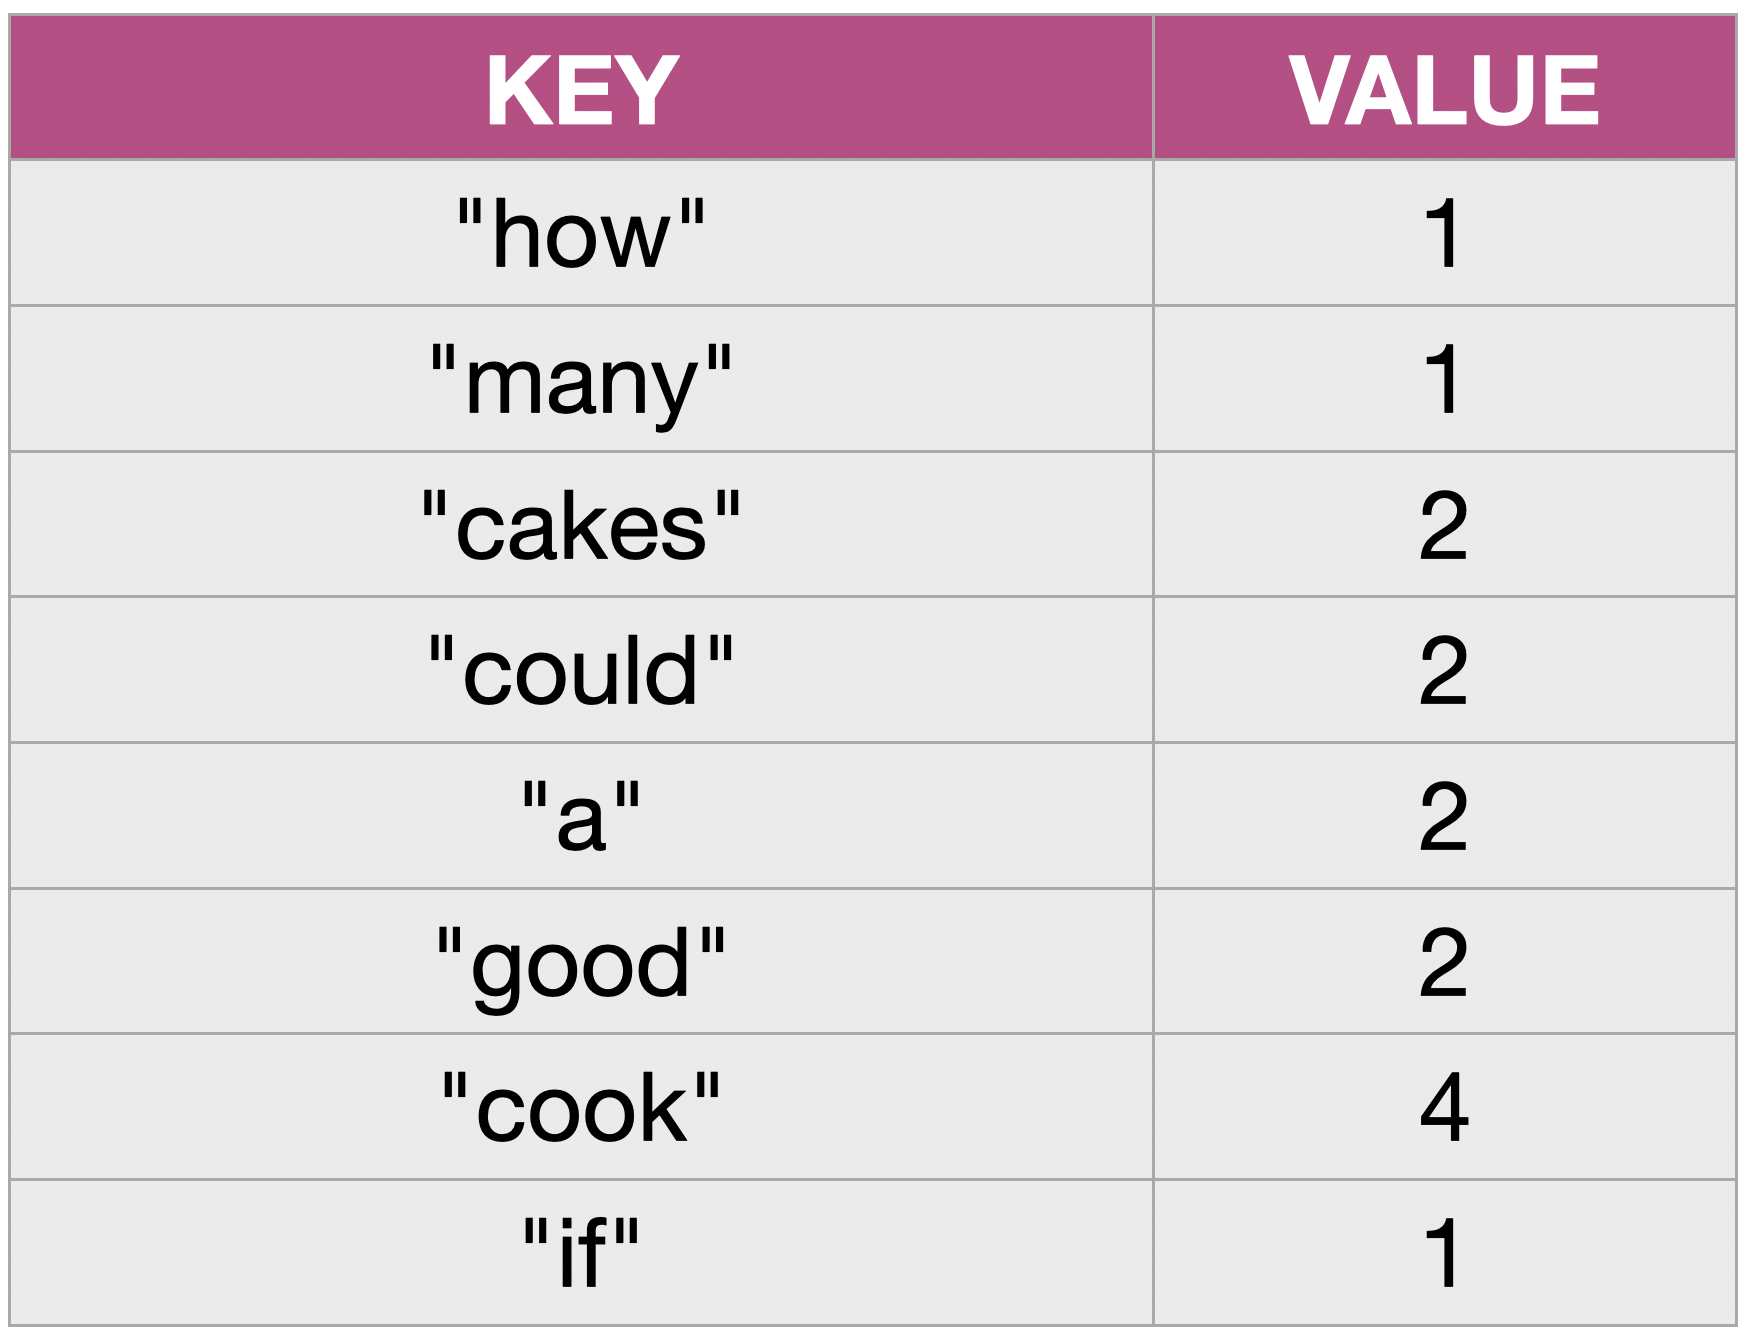
For example, a word count of the words in the sentence
"How many cakes could a good cook cook if a good cook could cook cakes?"
would result in the dictionary shown in Figure 2.4.
In other words: we will create a dictionary with one entry for every unique word in our text, where the value holds the number of times each word was used.
It is useful to remind ourselves that this dictionary – if we do a word count for a whole book – will hold thousands of entries. This, however, is not a problem: computers are good at dealing with large amounts of data.
The algorithm we will use can be informally described as follows:
You can modify your existing program to implement the algorithm described above by working step by step through the following exercises.
Exercise 2.10 We no longer wish to search for a single word, but count all words. Therefore, rename the count_word function to count_words and remove the first parameter (search_word).
Exercise 2.11 We will leave the first two lines of the function intact (the conversion to lowercase and creating a list of words in the text). Change the next line: instead of creating an integer variable count, we now create an empty dictionary called counts.
Exercise 2.12 We can leave the loop that iterates over all words in the text. We can also leave the code that strips the punctuation from the word. In the loop, however, we need to change our if-statement to do what the algorithm description above indicates: We need to check whether the word is already in our dictionary. We can do this using the in operator to check:
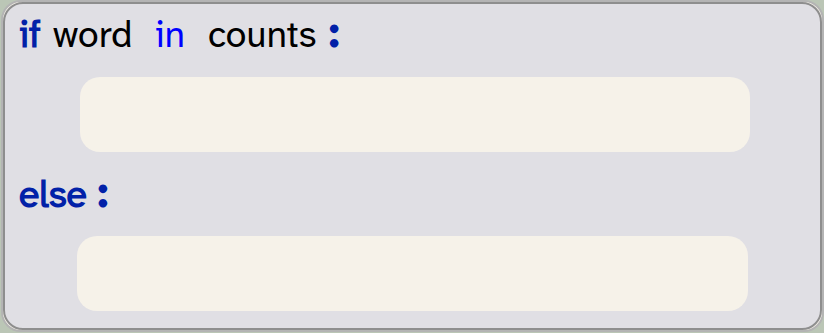
if word in counts:
    pass
else:
    pass
Exercise 2.13 We need to fill in the if-part of the if-statement: In this case, we need to increment the existing count for the word. We do this by reading the value for the word, adding 1, and writing it back into the dictionary:

counts[word] = counts[word] + 1Exercise 2.14 We then fill the else part with code to create a new entry for the word, with the value 1.
Exercise 2.15 At the end of the function, we now need to return the dictionary counts.
Exercise 2.16 Do not forget the comment: Modify the function comment to describe what your function now does.
Exercise 2.17 Test your function by modifying the code that calls it in the "My code" section. First, use a short test sentence, and print out the resulting word count dictionary.
Exercise 2.18 Now test the function on a whole book. Use, for example, the "/books/winnie-the-pooh.txt" file to count all the words in that book. Print out the dictionary.
A version of the project that implements these changes is available for you to study in the project folder as thematic-analysis-v3.
We can check whether a given key is present in a dictionary by using the in operator, like this: if key in dict. The in operator will return True or False.
Exercise 2.19 Look up what methods are available for Python’s dictionary class. What is the name of the method that returns a list of the keys in a dictionary? What is the name of the method returning only the values? What is the name of the method that lets you delete an entry with a given key?
 Advanced Python There are various ways in which we could simplify the loop in our function by avoiding the use of an if-statement.
One option is to use the get method with a default:

counts[word] = counts.get(word, 0) + 1Here, we use get to look up the value for a word, and we use 0 as a default value in case it is not found. This statement works whether or not the entry exists, so we do not need an if statement. Some practised programmers consider this version more elegant, while many beginners find the version with the if-statement clearer. If you are interested, look up the get method and analyse this line to understand how it works.
2.3. Iterating over dictionaries
We have seen that printing out the dictionary using a simple print call works, but the output is not very readable. The list of word counts is very long, and the formatting is not very readable. Let us improve this by implementing a custom printing function for our word count table.
Exercise 2.20 Create a new function called print_dict(dict) in your program. Its purpose is to print out a dictionary in a nicer layout. Write an appropriate function comment.
Exercise 2.21 In the body of this function, have a first try at printing out the dictionary entries. Test your function.
A first attempt at printing out the entries in our dictionary might involve printing each entry on a separate line:
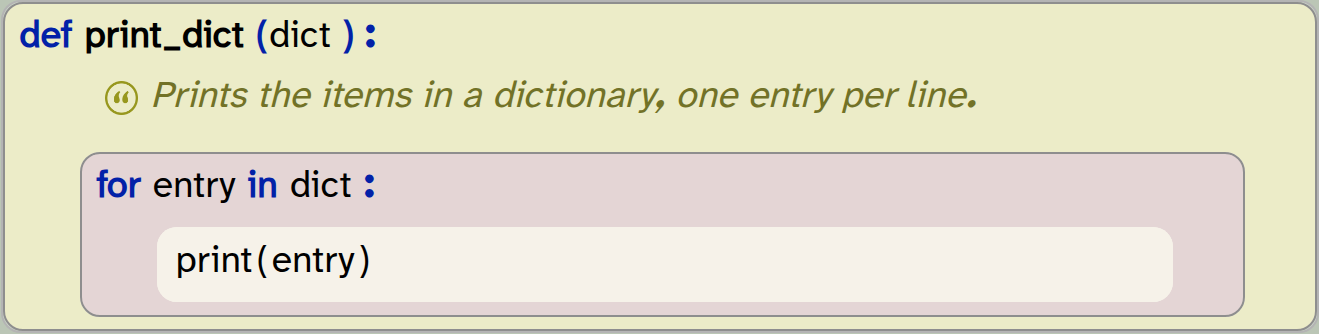
def print_dict(dict):
    '''Prints the items in a dictionary, one entry per line.'''
    for entry in dict:
        print(entry)
Exercise 2.22 Implement and test the print_dict version above. What do you observe?
With the above exercise, we can see that this version prints out the words in the dictionary, but not the counts. In other words: it prints the keys, but not the values of the dictionary.
How does this happen? Let us step back and take another look at the methods from the dictionary class that allow us to access its entries. There are three methods that give us lists of the dictionary contents:
| Method | Description |
|---|---|
|
Returns a list containing the dictionary’s keys |
|
Returns a list containing the dictionary’s values |
|
Returns a list of tuples of the dictionary entries, where every tuple contains a |
The first two of these show us that we can get a list containing just the keys or the values. This means that we could print out either the keys or the values, line by line, using these two loops:
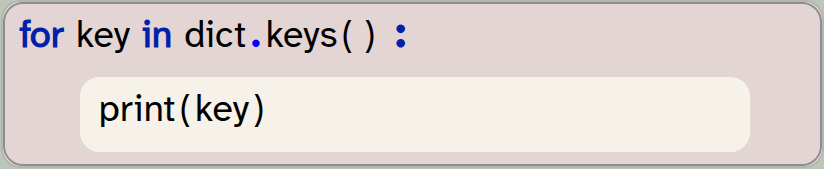
for key in dict.keys():
    print(key)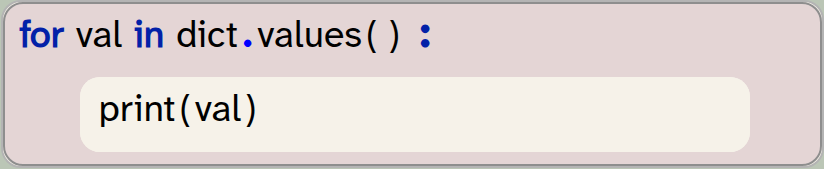
for val in dict.values():
    print(val)
Try this out. What we observed with the last exercise above is the following: If we just iterate over dict, without stating whether we want to get the keys or the values, we will get the keys by default.
Let us look at the third method: items(). This method states that it returns a tuple with the key and value. A tuple is another of Python’s collection types. It can hold multiple arbitrary data items to group them together. We will discuss tuples in more detail in the next chapter; for now it is sufficient to know that it consists of multiple data items and is written using round brackets:
( "Let It Be", "The Beatles", 1970 )
When we think about our dictionary, we can view a dictionary as a list of tuples. The first two entries of the dictionary shown in Figure 2.4, for example, can be regarded as two tuples:
( "how", 1 )
( "many", 1 )
Let us now try to use the items() method in our loop:
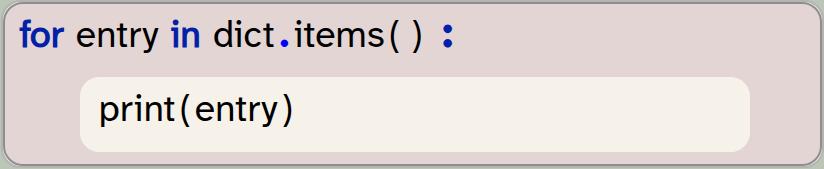
for entry in dict.items():
    print(entry)
Try this out. You will see that this loop prints each entry of the dictionary as a tuple.
Exercise 2.23 Implement and test the loop using the items() method.
This is, so far, the most useful method for us: it allows us to get the full data (key and value), and print them out line by line. But we can get even more control using an additional feature of the for-loop.
If we use a Python for-loop to iterate over a collection, and the item type of the collection is a tuple, then the loop can contain multiple loop variables:
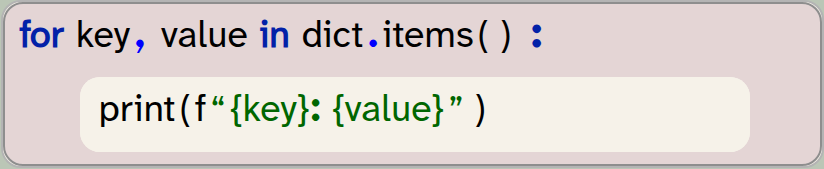
for key, value in dict.items():
    print(f"{key}: {value}")
The rules for this type of for-loop are quite straightforward:
-
The loop can provide a comma-separated list of loop variables.
-
Each item of the collection we iterate over must itself be a collection.
-
The number of loop variables must match the number of data items in each collection item. (In our case: Since each tuple in
dict.items()holds two pieces of data, we need exactly two loop variables.) -
The individual data items of each collection entry will be assigned to the loop variables for each iteration.
We can iterate over the entries in a dictionary by using the dict.items() method to get a list of all entries.
A for-loop can have multiple loop variables. In that case, the collection it iterates over must itself hold collections (tuples, sets or lists) of a matching length.
Using this variant of the for-loop allows us to get access to each key and value individually, and we are free to format the output ourselves. In the code example above, we have done this using an f-string.
Exercise 2.24 Implement this latest version of the for-loop. Test it with one of the full book texts as input.
Our output is now more nicely formatted. It is, however, still very long, and identifying frequently used words is still tricky. Change this by doing the following exercises.
Exercise 2.25 Change your print_dict function so that it prints out entries only if the word count is greater than 30.
The list is now much shorter, but it still contains a lot of very common words, such as "a", "to" and "the" – words that do not tell us much about what the text is concerned with. Let us do a first attempt at identifying interesting words by dropping all short words.
Exercise 2.26 Modify your print_dict function so that words shorter than five characters are ignored.
We can see that we are getting a bit closer. If you run this version of your program on one of the book texts provided, you can see that a list of words slowly emerges that may characterise the book. But the rules we have used to select the words (filtering by a word count that is more than a fixed value, and by length of the word) are not really good enough.
What we need to do instead is not look at the absolute frequency of a word (the number of times it appeared), but look for words that appear more often than they would in a typical English text. The word "the", for example, may appear very often, but it does so in all English writing, so this does not make it an especially interesting word.
This will be our goal in the next section: We will use existing statistics about expected word frequencies in the English language to identify "over-used" words in our text: words that are used more often in this text than they are used in average English texts.
2.4. Over-used words
In our project, we have provided a helper function called get_expected_frequencies(). This function returns a dictionary that lists the expected frequencies for the most common words in an average English language text. (It uses a dictionary of about 64,000 words.)
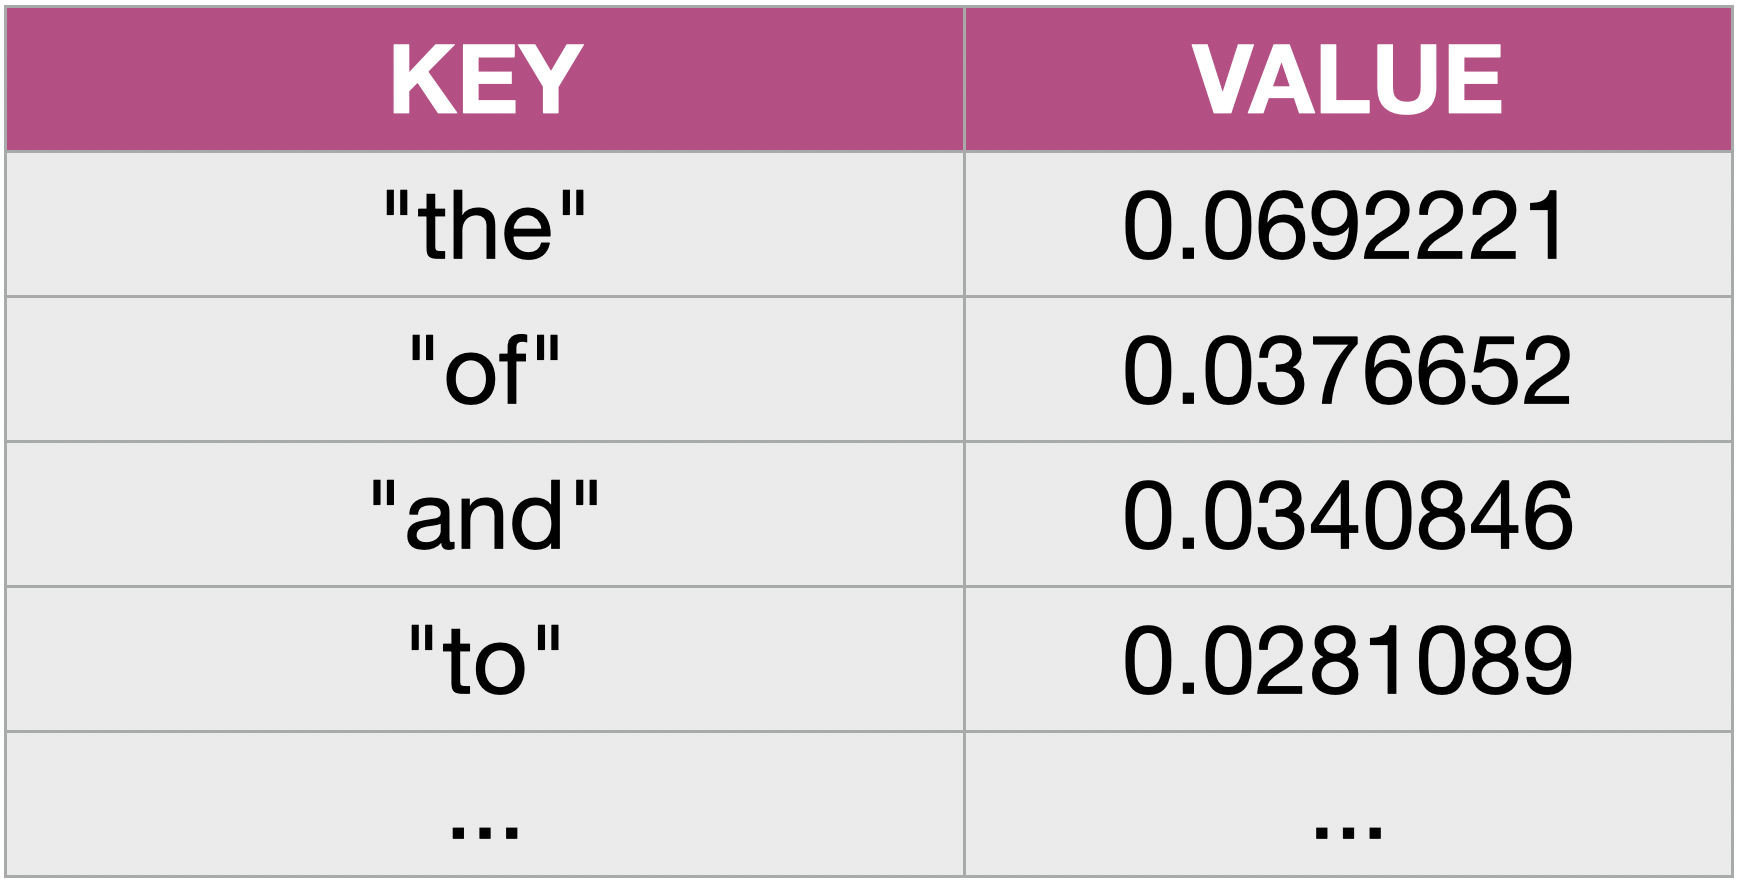
The dictionary has a word as its key, and the expected frequency as its value (Figure 2.5). The frequency here is the ratio of occurrences of the word relative to the length of the text. For example, as a percentage, the word "the" is around 6.9% of all words in a typical text. The ratio can be computed by dividing the word count by the total number of words in a text:
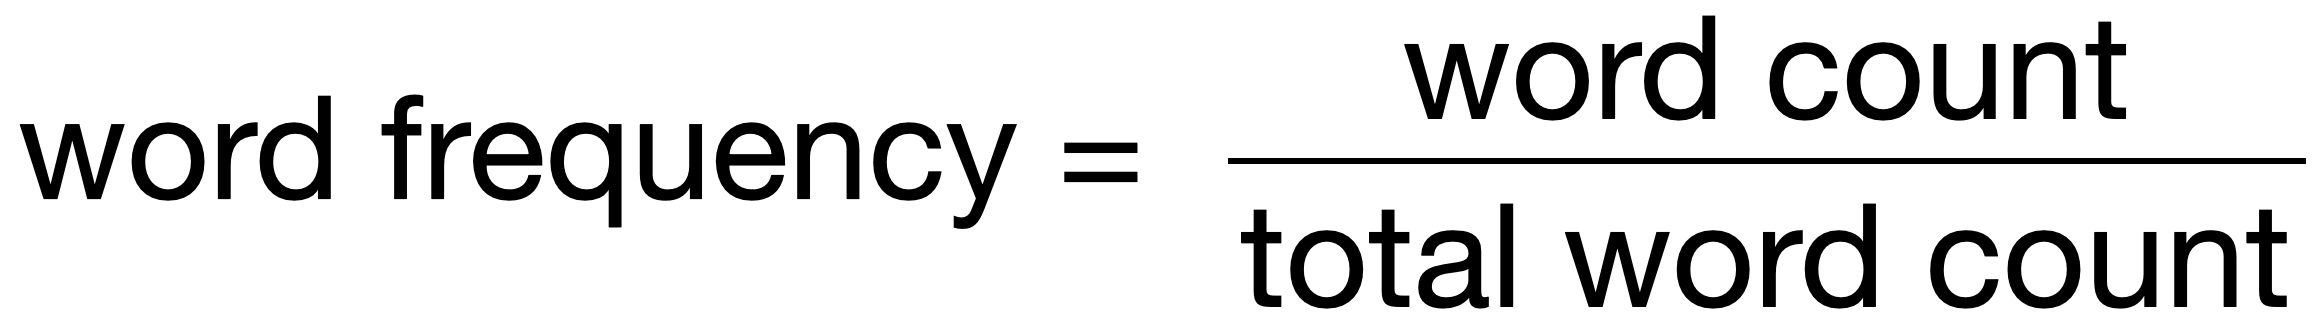
Using this formula, we can easily calculate the frequency of each word in the text we wish to analyse and then compare it to the expected frequency. Those words that are used far more often than expected are the "interesting words" – the words that might give us a clue to what the text is about.
Let us go ahead and implement this idea. We will identify the frequent words, which we define as words with a frequency that is at least 10 times the expected frequency and which were used at least 10 times.
Exercise 2.27 Add a new function called get_overused_words that takes three parameters: an observed_counts dictionary of word counts in the text under investigation, the total number of words in our text (total_words), and a frequencies dictionary of word frequencies in the English language:
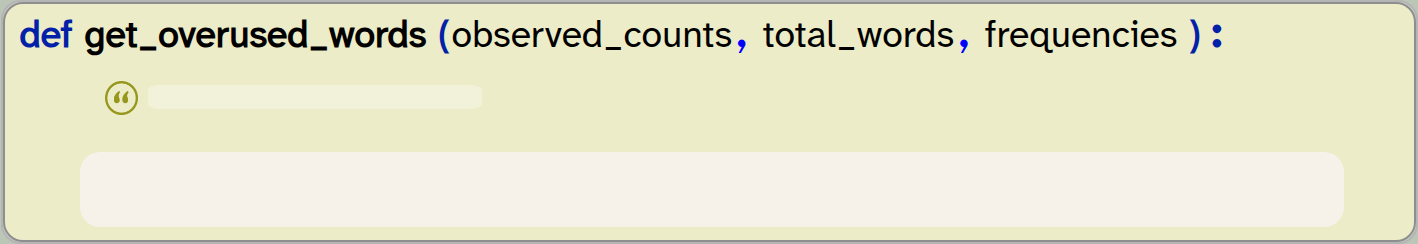
def get_overused_words(observed_counts, total_words, frequencies):
    pass
Add an appropriate comment.
Exercise 2.28 Add a loop inside the function that iterates over the entries in the observed word list. We can use the pattern with two loop variables, as discussed above:
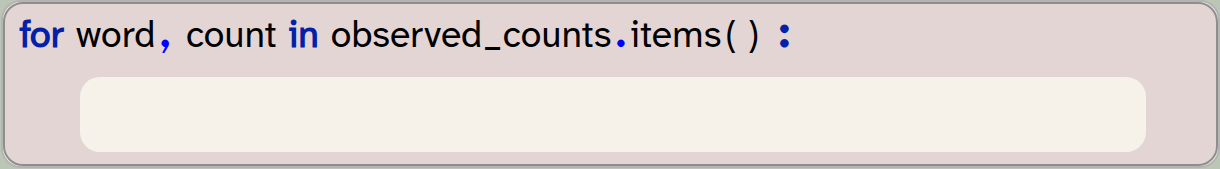
for word, count in observed_counts.items():
    pass
Exercise 2.29 Inside the loop, add an if statement that checks if the word is in the frequencies dictionary. If it is, compute the actual frequency of the word in the text (count / total_words) and store it in a variable.
Exercise 2.30 At the beginning of your function, create an empty dictionary called frequent. This will be used to collect the frequent words and their word counts. Inside the loop, add each word to this dictionary if it is used at least 10 times and if its frequency is at least 10 times the expected frequency. At the end of your function, return this dictionary.
Exercise 2.31 In the "My code" section, add code to call and test this function. To do this, you will need to calculate the total number of words in your text. You can do this easily as follows:

total_words = len(text.split())Print out the dictionary of frequent words.
2.5. Finding the most over-used words
With the code so far, we can print out the dictionary of frequent words. We have, however, no direct control over the exact number of words we will receive. This will depend on the length of the actual text and the words within it.
Let us make one last improvement to specify exactly how many words we wish to see. To do this, we will sort the frequent words by their word count, and then select the top words from this list.
We can do this by making good use of Python’s built-in sorted function:
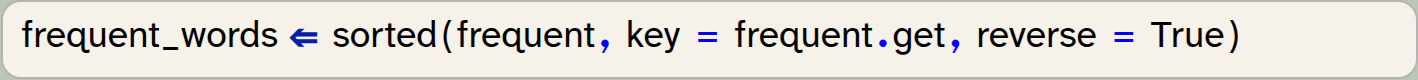
frequent_words = sorted(frequent, key=frequent.get, reverse=True)We can add this statement to our get_overused_words function to create a list of the frequent words, sorted by their word count.
This is quite an advanced use of this function, so let us investigate that line in some detail.
-
We use the built-in
sortedfunction. This function takes a list and returns a sorted copy of that list. (It is important to note that it does not sort the original list, but returns a sorted copy.) -
We pass a dictionary to this function, which expects a list. If this function receives a dictionary, it will sort just the keys from the dictionary.
-
The
sortedfunction allows us to specify akeyas a parameter. The key is a function that is used to sort the list. Here, we usefrequent.getas the key; this is the dictionary method that returns the value from the dictionary, thus the keys will be sorted by their associated value. -
We set the
reverseparameter toTrueto sort the list in descending order, with the highest values first.
The sorted function returns a sorted copy of a list. It has optional parameters to specify a sort function and the sort order.
After doing this, we can use a slice to take the first few elements. For example

frequent_words[:12]will give us the 12 most frequent words. We can then return this list from our function.
Exercise 2.32 Make the changes discussed here to your code. Add another parameter to your get_overused_words function to specify how many words you wish to receive. Note that the function now returns a list, not a dictionary! You will need to modify your test code accordingly.
Exercise 2.33 Format the output of your program nicely, so that it prints the title of the book you are evaluating (or the name of the file), and then the most over-used words as identified by your function.
In making these changes, it is likely that you ran into a number of errors. This is to be expected. We have made many changes, and we will always make errors along the way. It is not the goal to write our code error-free at the first attempt, but to get to know Python well enough that we can identify and fix any errors that occur. So do not worry if it takes you many iterations of writing code, running, getting error messages and fixing errors to get to the eventual result.
Exercise 2.34 Try your code on the other books provided in Strype’s "/books" folder. (They include, for example, "/books/three-men-in-a-boat.txt" and "/books/war-and-peace.txt".) Also try some text you have written yourself, such as a story or essay.
Once you manage to complete these tasks, you will see that you can now get a vague impression what a book is about. You can see that War and Peace is about a prince, a princess, an emperor and Napoleon, or that Three Men in a Boat is about a boat, a picture, locks and rowing.
A version of this project that includes all the changes discussed here is available as thematic-analysis-v4; you may like to compare your own version to this one.
2.6. Summary
In this chapter, we have learned how to use dictionaries to achieve more advanced functionality.
Dictionaries are perhaps a little more unusual than lists, but they are equally useful. To become a good programmer, it is important to become familiar with dictionaries, and fluent in using them. They should be one tool in your standard toolbox, so that you can use them whenever they can help to solve a problem. You will see that they come in handy more often than you initially expect.
-
A dictionary is a data structure that holds key/value pairs. We can look up a key to find the associated value.
-
Python dictionaries are written using curly brackets: { }. Writing a pair of curly brackets on their own creates an empty dictionary.
-
A key in a dictionary is unique, but values can appear repeatedly. Inserting an entry with a key that already exists replaces the existing entry.
-
We can check whether a given key is present in a dictionary by using the in operator, like this: if key in dict. The in operator will return True or False.
-
We can iterate over the entries in a dictionary by using the dict.items() method to get a list of all entries.
-
A for-loop can have multiple loop variables. In that case, the collection it iterates over must itself hold collections (tuples, sets or lists) of a matching length.
-
The sorted function returns a sorted copy of a list. It has optional parameters to specify a sort function and the sort order.
Top 10 songs
We have now seen how we can analyse some data. In the case of the text analysis here, the data source is English text. In other cases (such as the temperature data used in the previous book volume), the data might be numbers, but it was also read from a plain text file.
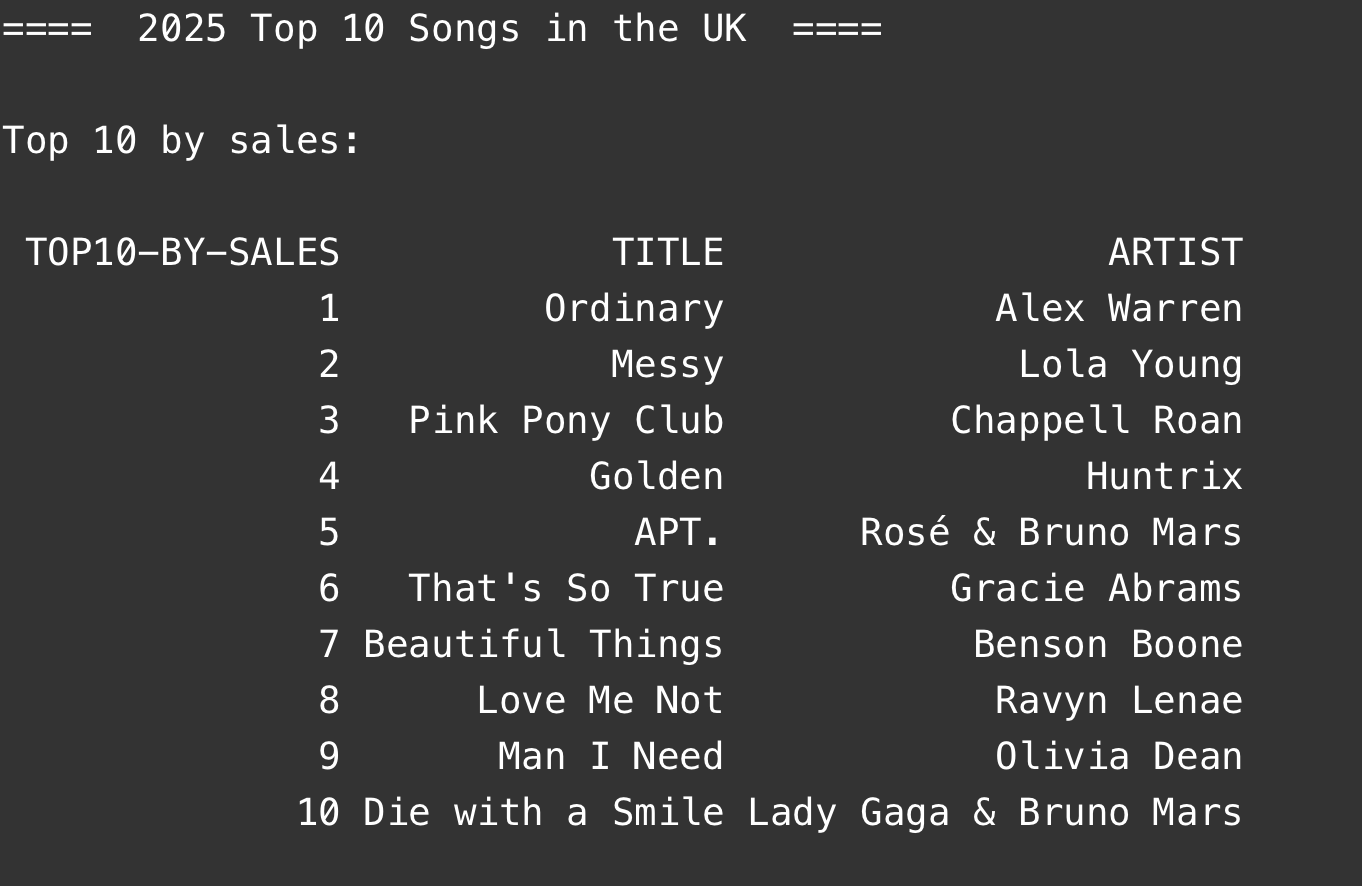
In real life, data is often stored in specific formats, and one of the most common is a file of comma-separated-values (in a file with a .csv suffix). Python has powerful libraries to read and analyse those files. This project, top-10-songs, shows how to use the pandas library to read and analyse such a file. And all without writing a single loop! If you are interested in more sophisticated data analysis, it is worth getting to know this library.
If you would like to research this further, you may also be interested to look at the (much more sophisticated) "renewables" project shown in Chapter 7.